
March 2026
Connector SDK
fivetran-connector-sdk PyPI package
We have released version 2.7.2 of the fivetran-connector-sdk PyPI package. This release includes the following updates:
- Security fixes for vulnerabilities in
requestspackage. - Improved overall performance and stability.
- Minor enhancements and improvements.
- Updated testers.
We have released version 2.7.1 of the fivetran-connector-sdk PyPI package. This release includes the following updates:
- Improved logging for
fivetran debugandfivetran reset - Minor enhancements and improvements.
- Updated tester - fixed vulnerabilities and logging.
We have released version 2.7.0 of the fivetran-connector-sdk PyPI package. This release includes the following updates:
- Changes the default Python version to 3.13 since the Performance Profiling feature uses
py-spy, which is not supported by Python versions > 3.13. You can still change the runtime Python version to 3.14 by using--python-versionargument passed tofivetran deploycommand or directly from the setup form after deployment. - Minor enhancements and improvements.
We have released version 2.6.2 of the fivetran-connector-sdk PyPI package. This release includes the following updates:
- A new help command for the PyPI package that provides users with additional information about the package and its usage.
- Improved error handling and logging.
- Better handling of conflicting packages.
- Minor enhancements and improvements.
Fivetran Connector SDK
Connector SDK connectors now support VPN tunnel as a connection option. A VPN tunnel provides a secure, encrypted site-to-site VPN connection between your network and Fivetran's network, enabling your connector code to access your source over a private network. You must have an Enterprise or Business Critical plan to use a VPN tunnel connection for Connector SDK.
We've enabled performance profiling for Connector SDK syncs. You can now analyze CPU usage and code execution time using flamegraphs generated via py-spy, available for production syncs (if supported) and local debugging.
For more information, including how to analyze flamegraphs, see our Performance Profiling documentation.
fivetran-api-playground PyPI package
We have released version 1.1.4 of the fivetran-api-playground PyPI package. This release adds the following:
- Upgrades the flask library dependency to 3.1.3 .
- Upgrades the faker library dependency to 40.4.0 .
- Upgrades the colorama library dependency to 0.4.6 .
We have released version 1.1.5 of the fivetran-api-playground PyPI package. This release adds support for session token expirations. Session tokens now expire after 1 hour, and the login endpoint returns an expires_in field indicating the token's validity period.
Dashboard Improvements
Schema change details in events list
You can now view detailed information about schema changes directly on the Connection Status tab in the Fivetran dashboard. When you click on a schema change event in the events list, a detail view displays the total count of changes and organizes them into categories:
- Schemas: Schemas that were enabled or disabled
- Tables: Tables that were selected or deselected for syncing
- Columns: Columns that were enabled or disabled, and changes to column hashing and encryption settings
- Sync modes: Changes to table sync settings (soft delete, history mode, or live sync)
This read-only view allows you to see exactly what was changed in a schema update without leaving the Status page.
If a schema change includes a large number of modifications, some details may be truncated to improve performance. When this occurs, the detail view displays a notice indicating that not all changes are shown.
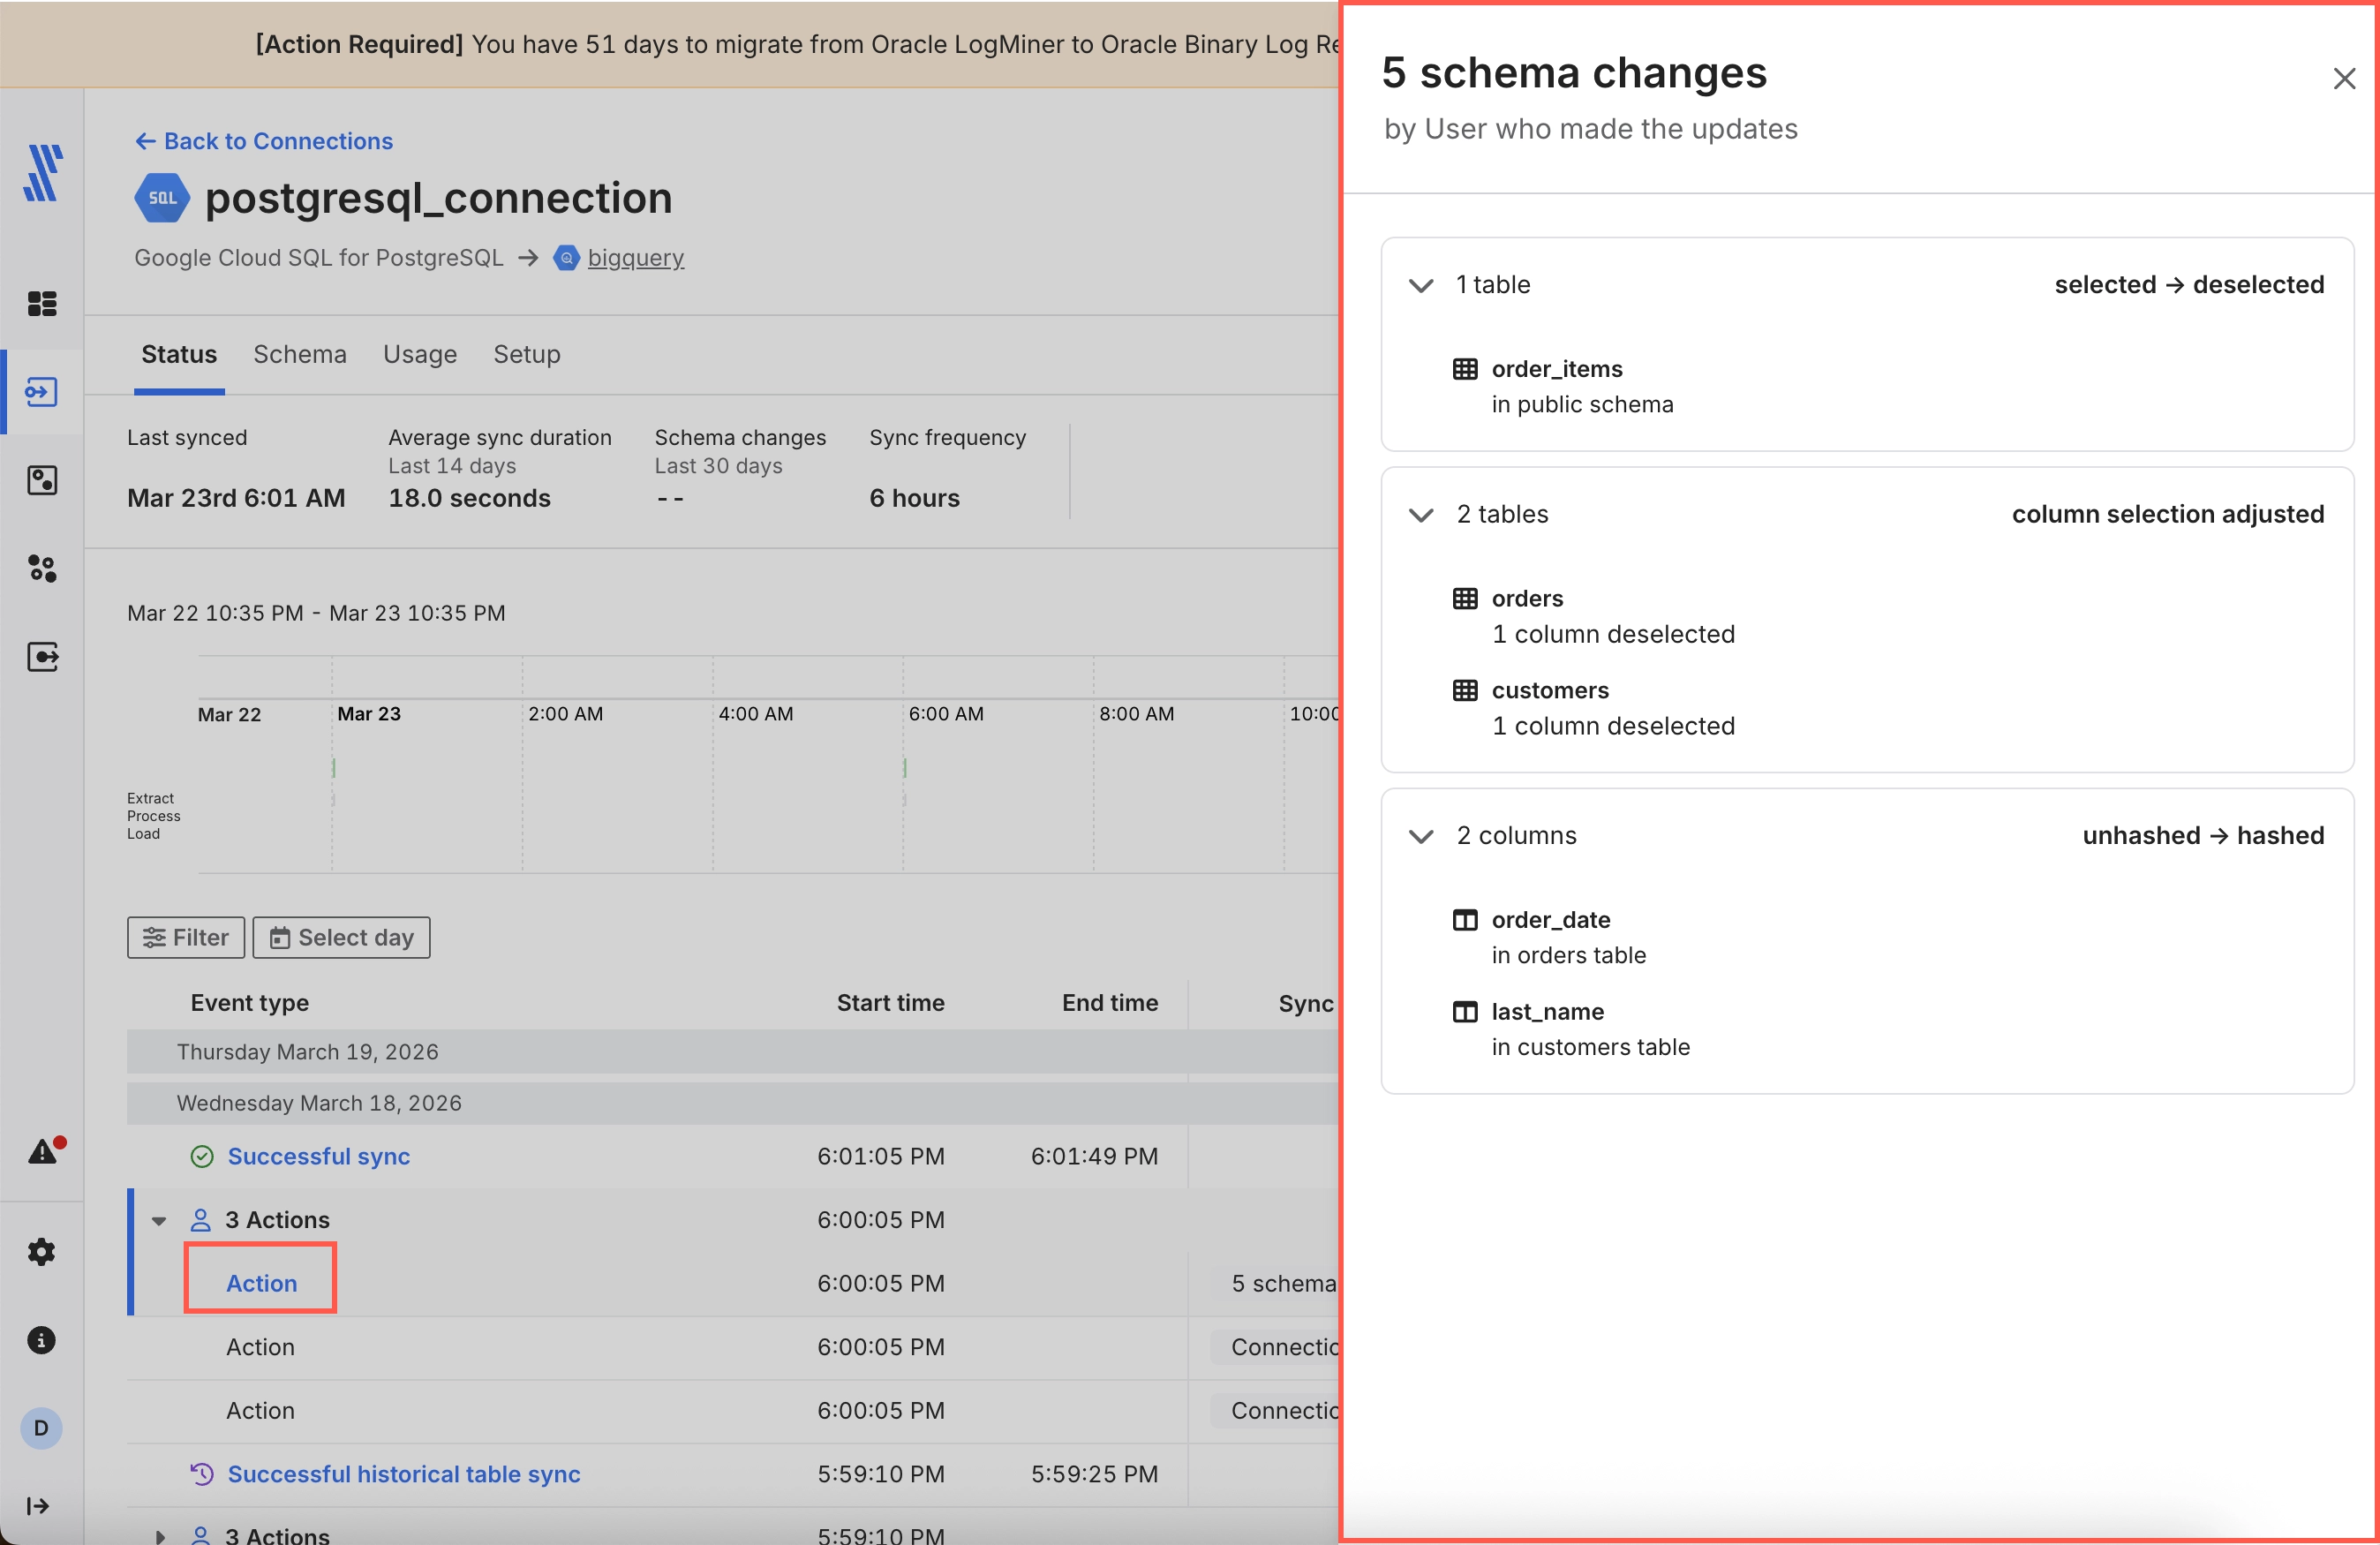
For more details, see our Connection Status documentation.
Lite Connectors
Lite connectors are now available for the following sources:
Logs
Azure Monitor
Our Azure Monitor external logging service now supports the Log Ingestion API. The Log Ingestion API replaces the legacy Data Collector API and provides improved reliability, flexibility, and support for Data Collection Rules (DCR)-based log routing.
We recommend that you migrate to the new flow because Microsoft plans to retire the legacy Data Collector API in September 2026.
Datadog
We've added support for the AP2 region for the Datadog external logging service.
Grafana Loki External Logging
We now support Grafana Loki as an external logging service. You can connect Grafana Loki at both the account and destination levels to collect and query your Fivetran logs. We are gradually rolling out this feature to all accounts.
To set up Grafana Loki logging services, go to Account Settings > General > External Logging or go to your destination settings in your Fivetran dashboard. For more information, see our Grafana Loki Setup guide.
Query execution time in extract_summary log event
The extract_summary log event now includes two new execution time fields for database connectors:
total_execution_time— the total accumulated query execution time in milliseconds across all tables during the sync.execution_time— the accumulated query execution time in milliseconds for each individual entry in theobjectsarray.
These fields give you visibility into which tables have the highest query execution cost, helping you identify performance bottlenecks at the table level.
The execution_time and total_execution_time fields are only available for database connectors. The objects field itself is not available for all connectors. If you need a specific connector to support this field, submit a feature request.
Partner SDK
Partner-Built Program
At this time, we are not accepting new submissions to the Partner-Built program.
MotherDuck
The MotherDuck destination is now in beta.
Read our MotherDuck destination documentation.
Quickstart Package Updates
Quickstart data model package updates
v1.3.1
Documentation
- Removes dynamic
count_visitors_*columns from thependo__guideandpendo__guide_daily_metricsmodels inpendo.ymlto preventpersist_docserrors when these columns are not present.
v1.4.1
Documentation
- Removed documentation from
zendesk.ymlfor dynamic columns fromzendesk__ticket_field_historyandzendesk__ticket_backlogto preventpersist_docserrors when these columns are not present.
v0.6.3
Bug Fix
- Fixes a SQL compilation error on BigQuery in the
bsidandbsadmodels to cast_dataagingto string to avoid datatype failures, ensuring consistent types regardless of how the source column is synced.
v0.1.0
Bug Fix
- Updates the
string_mappingmacro to pass a warning in cases where no mapping fields are found.
Under the Hood
- Updates integration tests and seed data to test when no string mapping fields are found.
v1.5.2
Documentation
- In the
quickstart.ymlfile:- Made several corrections to Quickstart
supported_varsdescriptions to reflect correct time granularity forjira_issue_history_bufferandlookback_windowvariables.
- Made several corrections to Quickstart
v1.4.2
Bug Fix
- Fixes PostgreSQL compatibility issue in
get_url_tags_query()macro wherejsonbcolumns were incorrectly processed usingjson_array_elements()instead ofjsonb_array_elements(), causing database errors whenurl_tagscolumn is stored asjsonbdatatype.
v1.6.1
Bug Fix
- Updates the
subscription_discountsource column reference fromcheckout_session_idtocheckout_sessionto match the raw Stripe source naming convention. The output column namecheckout_session_idis preserved as an alias in the staging layer, so there is no downstream impact.
v0.6.2
Documentation
- Adds missing, removes stale, and corrects column-level descriptions for the following models:
marcmchbmkpfmsegsap__0fi_gl_14sap__0material_attrstg_sap__bsegstg_sap__dd07lstg_sap__dd07tstg_sap__marcstg_sap__mchbstg_sap__mchp
v0.3.2
Documentation
- Updates column descriptions for
line_item_line_item_typeand related fields to be more concise. - Updates README to remove badges and replace with plain-text dbt Core version compatibility.
Under the Hood
- Adds a
persist_docsconditional to integration tests to enable relation and column documentation persistence, except for Databricks targets.
v1.3.3
Documentation
- Updates
user_idcolumn descriptions instg_amplitude,amplitude_event_enhanced, andamplitude_session_enhancedfor clarity and conciseness. - Updates the README to remove badge images and add dbt Core™ supported version information in plain text.
Under the Hood
- Adds
persist_docsconfiguration tointegration_tests/dbt_project.ymlto validate column-level documentation persistence.
v1.7.2
Schema/Data Change
1 total change • 0 possible breaking changes
| Data Model(s) | Change type | Old | New | Notes |
|---|---|---|---|---|
stg_hubspot__contact | Changed field | merged_object_ids (string or integer) | merged_object_ids (string) | HubSpot can sync this field as an integer when no contacts have been merged. Casting to string prevents runtime errors in the downstream merge_contacts() macro where the split function requires a string. |
v0.8.2
Feature Updates
- Updates the
quickstart.yml:- Adds
workday__employee_daily_history,workday__monthly_summary, andworkday__worker_position_org_daily_historyto the list of public models. - Adds
supported_varsentry foremployee_history_start_dateto allow users to configure the employee history start date in Quickstart. - Adds
employee_history_enabledtable variables forworker_history,worker_position_history, andpersonal_information_historyto prevent missing sources from blocking downstream Quickstart models.
- Adds
v1.5.1
Bug Fix
- Fixes non-deterministic SLA reply time calculations in
int_zendesk__reply_time_business_hoursandint_zendesk__reply_time_combinedfor tickets with multiple SLA policies. Previously,lapsed_business_minutesand breach calculations mixed results across policies when the sameticket_id,metric, andsla_applied_athad more than onesla_policy_name. Window functions now partition bysla_policy_nameto correctly isolate each policy's calculation.
v1.4.1
Bug Fix
- Updates URL tag processing to handle native JSON datatypes across all supported warehouses, preventing errors when
url_tagscolumns are stored as JSON/JSONB/VARIANT/SUPER instead of strings.
Feature Update
- Adds the
get_column_datatype()macro to retrieve the datatype of a specific column. - Updates the
get_url_tags_query()macro with datatype detection to handle both native JSON columns and JSON-like string columns across BigQuery (JSON), Snowflake (VARIANT), Redshift (SUPER), and PostgreSQL (JSONB).
Under the Hood
- Adds native JSON testing to
integration_tests. - Updates the
vertical_sum_conversion_valueintegrity test to validate bothconversions_valueandconversions.
v1.6.0
Schema/Data Change (--full-refresh required after upgrading)
1 total change • 1 possible breaking change
| Data Model(s) | Change type | Old | New | Notes |
|---|---|---|---|---|
jira__daily_issue_field_history | Incremental filter fix (Breaking Change) | Filtered by date_day >= max_date_week | Filtered by date_week >= max_date_week | Aligns the incremental filter with the model's weekly partition key. The previous filter could cause data loss during partition overwrites in BigQuery and Databricks destinations on incremental runs. could cause data loss during partition overwrites on incremental runs. A full refresh is recommended to backfill any records that may have been missed. |
v1.5.0
Schema/Data Change
4 total changes • 2 possible breaking changes
| Data Model | Change type | Old | New | Notes |
|---|---|---|---|---|
int_zendesk__ticket_first_resolution_time_business (Breaking) | Removed model | Consolidated into int_zendesk__ticket_resolution_time_business_combined. This table will no longer be updated in your target warehouse and can be dropped manually if desired. | ||
int_zendesk__ticket_full_resolution_time_business (Breaking) | Removed model | Consolidated into int_zendesk__ticket_resolution_time_business_combined. This table will no longer be updated in your target warehouse and can be dropped manually if desired. | ||
int_zendesk__ticket_resolution_time_business_combined | New model | Consolidates int_zendesk__ticket_first_resolution_time_business and int_zendesk__ticket_full_resolution_time_business into a single model that outputs both fields: first_resolution_business_minutes and full_resolution_business_minutes, improving model runtime. | ||
int_zendesk__ticket_historical_status | Deprecated fields | ticket_status_counter, unique_status_counter | Columns are deprecated as of March 2026 and will be removed in a future release. See Github Issue for details. |
Under the Hood
- Replaces reference to
stg_zendesk__userwithint_zendesk__user_aggregatesinzendesk__ticket_summaryto better align with dbt best practices and reduce DAG complexity.
v1.4.2
Bug Fixes
- With variable configuration now available in Quickstart, the
quickbooks__home_currencyvariable from the v1.1.1-a2 pre-release is now available across all 13 intermediate double-entry transaction models to optimize multi-currency handling. When the variable is set, transactions in the designated home currency will not apply exchange rate conversions onconverted_amount, improving accuracy. When left empty, all transactions will see exchange rate conversions applied. (PR #197)- Updates the README with instructions for configuring the
quickbooks__home_currencyvariable.
- Updates the README with instructions for configuring the
- Applies fixes in
int_quickbooks__sales_receipt_double_entrymodel to correctly referencequickbooks__global_tax_account_referenceandquickbooks__sales_tax_account_referencevariables. (PR #197) - Introduces the
partition_by_source_relationmacro to conditionally includesource_relationin window function PARTITION BY clauses only when multiple sources are configured via thequickbooks_union_schemasandquickbooks_union_databasesvariables. This resolves partition by constant expression errors on Redshift. See the README on how to leverage these variables. (PR #198)
Under the Hood
- Changes default
quickbooks__home_currencyvalue to empty string for easier understanding within Quickstart UI. (PR #197)
v1.6.0
Schema/Data Changes
3 total changes • 0 possible breaking changes
| Data Model(s) | Change type | Old | New | Notes |
|---|---|---|---|---|
stripe__subscription_item_mrr_report | Changed data | Discount sourced from discount table | Discount sourced from subscription_discount table | Affects discount-based MRR calculations for subscriptions with active coupons. |
stg_stripe__subscription_discount | New Staging Model | Staging model for subscription discount data. This table is enabled by default, and can be disabled via variable configurability. See the README for more details. | ||
stg_stripe__subscription_discount_tmp | New Temp Model |
Bug Fixes
- Removes
convert_valuesmacro fromamountcalculation instripe__subscription_item_mrr_report. The macro is already applied at the staging layer and applying it to the metric calculation was causing a double conversion, leading to potential undercalculation of MRR values whenstripe__convert_valueswas set to true. - Adds
convert_valuesmacro toamount_offfield value instg_stripe__coupontable to ensure correct conversion of discounted amount when customers have the variable set to true.
Under the Hood
- Updates
int_stripe__subscription_discountto source from thesubscription_discounttable via the newstg_stripe__subscription_discountstaging model, instead of sourcing from thediscounttable viastg_stripe__discount. - Adds integration test seed files
subscription_discount_data.csv,subscription_discount_data_snowflake.csv, andsubscription_discount_data_postgres.csv.
v1.7.0
Schema/Data Change (--full-refresh required after upgrading)
3 total changes • 3 possible breaking changes
| Data Model(s) | Change type | Old | New | Notes |
|---|---|---|---|---|
jira__daily_issue_field_history jira__daily_sprint_issue_history jira__issue_enhanced | Removed default columns (Breaking Change) | story_points and story_point_estimate included by default | Columns only included when added to var('issue_field_history_columns') | These fields are Scrum-specific custom fields not universally used. Add the relevant fields to the issue_field_history_columns variable to retain them. |
jira__sprint_enhanced | Removed default columns (Breaking Change) | story_points_committed, story_points_end, story_points_completed, story_point_estimate_committed, story_point_estimate_end, and story_point_estimate_completed included by default | Columns only included when story points and/or story point estimate are added to var('issue_field_history_columns') | These metrics depend on story_points/story_point_estimate being tracked in field history. Add the relevant fields to the issue_field_history_columns variable to retain them. |
jira__daily_sprint_issue_history jira__sprint_enhanced | Column type change | story_points and story_point_estimate cast as float | Cast as numeric | Improves precision for fractional story point values. |
Bug Fix
- Updated
stg_jira__sprintto filter out soft-deleted sprint records using the_fivetran_deletedflag.
Under the Hood
- Adds a new
convert_string_to_numericmacro with warehouse-specific dispatch implementations to safely cast story point string values to numeric, handling edge cases such as comma-formatted numbers.
Documentation
- Updates model descriptions to remove static documentation for
story_points,story_point_estimate, andteamcolumns. Removes story point-related column documentation fromjira__sprint_enhancedas these columns are dynamic and only present when added tovar('issue_field_history_columns').- To retain story point data, add
story pointsand/orstory point estimateto theissue_field_history_columnsvariable in yourdbt_project.yml(See the README for details). Quickstart users can add these fields in the Issue Field History Columns setting.
- To retain story point data, add
v1.4.0
Schema Changes
5 total changes • 0 possible breaking changes
| Data Model | Change type | Old | New | Notes |
|---|---|---|---|---|
stg_zendesk__ticket_chat | New Columns | initiator | Reflects the persona that initiated the conversation (agent, end user, or system). | |
stg_zendesk__sla_policy_metric_history | New staging model | Tracks historical changes to SLA policy targets at various ticket priority levels. Can be disabled by setting the using_sla_policy_metric_history variable to False. | ||
stg_zendesk__ticket_sla_policy | New staging model | Tracks which SLA policies have been applied to tickets and when they were applied. Can be disabled by setting the using_ticket_sla_policy variable to False. | ||
stg_zendesk__sla_policy_metric_history_tmp | New temp staging model | Tracks historical changes to SLA policy targets at various ticket priority levels. Can be disabled by setting the using_sla_policy_metric_history variable to False. | ||
stg_zendesk__ticket_sla_policy_tmp | New temp staging model | Tracks which SLA policies have been applied to tickets and when they were applied. Can be disabled by setting the using_ticket_sla_policy variable to False. |
Feature Update
- Adds support for the
sla_policy_metric_historyandticket_sla_policysource tables to enable more granular SLA policy tracking based on ticket priority levels.- These new tables are dynamically enabled in Fivetran Quickstart based on whether they are being actively synced. For dbt Core users, the tables are enabled by default but can be disabled with the following configuration in your
dbt_project.yml:
- These new tables are dynamically enabled in Fivetran Quickstart based on whether they are being actively synced. For dbt Core users, the tables are enabled by default but can be disabled with the following configuration in your
vars:
  using_sla_policy_metric_history: false
  using_ticket_sla_policy: false
- Adjusts SLA policy logic to use the current ticket priority level's targets for calculating metrics. Previously, targets were taken from the priority that a ticket was first assigned to.
Bug Fixes
- Updates Snowflake regex parsing in the
extract_schedule_day()macro. - Aligns with Zendesk's method of calculating agent replies and comment metrics for messaging/chat. Previously, we counted each individual chat message as a distinct comment. In accordance with Zendesk's docs, we now count active conversation sessions.
- For example, if an agent sends three messages in the same active conversation and then the conversation ends, that exchange counts as one Agent reply. Previously, we would have counted three replies.
v1.4.0
Schema/Data Change
22 total changes • 21 possible breaking changes
| Data Model(s) | Change type | Old | New | Fields affected |
|---|---|---|---|---|
recurly__account_overview | Data type | float | numeric | total_charges, total_credits, total_balance, total_discounts, charges_this_month, credits_this_month, balance_this_month, discounts_this_month |
recurly__account_overview | Data type | int | numeric | total_taxes, taxes_this_month |
recurly__account_daily_overview | Data type | float | numeric | daily_net_change, daily_charges, daily_credits, daily_discounts, rolling_account_balance, rolling_charge_balance, rolling_credit_balance, rolling_discount_balance |
recurly__account_daily_overview | Data type | int | numeric | daily_taxes, rolling_tax_balance |
recurly__balance_transactions | Data type | float | numeric | amount, credit_applied, discount, unit_amount |
recurly__balance_transactions | Data type | int | numeric | tax, subtotal |
recurly__monthly_recurring_revenue | Data type | float | numeric | current_month_mrr, previous_month_mrr |
recurly__subscription_overview | Data type | float | numeric | unit_amount |
recurly__subscription_overview | Data type | int | numeric | add_ons_total, subtotal |
recurly__line_item_enhanced | Data type | float | numeric | unit_amount, discount_amount, total_amount |
recurly__line_item_enhanced | Data type | int | numeric | tax_amount, refund_amount |
recurly__line_item_enhanced | Logic update | line_item_index ordered by created_at only | line_item_index ordered by created_at, then line_item_id | Ensures deterministic ordering when multiple line items share the same created_at timestamp |
int_recurly__transactions_grouped | Data type | float | numeric | daily_charges, daily_credits, daily_balance, daily_discounts |
int_recurly__transactions_grouped | Data type | int | numeric | daily_taxes |
int_recurly__account_cumulatives | Data type | float | numeric | total_charges, total_credits, total_balance, total_discounts, charges_this_month, credits_this_month, balance_this_month, discounts_this_month |
int_recurly__account_cumulatives | Data type | int | numeric | total_taxes, taxes_this_month |
int_recurly__account_rolling_totals | Data type | float | numeric | daily_charges, daily_credits, daily_balance, daily_discounts, rolling_account_balance, rolling_charge_balance, rolling_credit_balance, rolling_discount_balance |
int_recurly__account_rolling_totals | Data type | int | numeric | daily_taxes, rolling_tax_balance |
int_recurly__account_running_totals | Data type | float | numeric | daily_charges, daily_credits, daily_balance, daily_discounts, rolling_account_balance, rolling_charge_balance, rolling_credit_balance, rolling_discount_balance |
int_recurly__account_running_totals | Data type | int | numeric | daily_taxes, rolling_tax_balance |
All stg_recurly__* models | Data type | float | numeric | amount, balance, credit_applied, discount, setup_fees, unit_amount |
All stg_recurly__* models | Data type | int | numeric | add_ons_total, discount, paid, refundable_amount, subtotal, tax, total |
Under the Hood
- Corrected
get_*_columnsmacro fields forinvoice_history,line_item_history,subscription_historythat were cast asintinstead offloatto match the Recurly API type (number <float>).
Documentation
- Fixes link to
streamlit_fivetran_billing_modelrepo in the README.
Quickstart Transformations
Custom naming convention for Quickstart Data Models
We have added support for custom schema naming convention in Quickstart Data Models. You can now define the naming convention of the schema in the destination where your staging and transformed models will land. For more details, see the Edit Schema Naming Conventions for Quickstart Transformations section.
Table and column descriptions persisted to destinations for Quickstart Data Models
Quickstart Data Models now automatically persist table descriptions as table comments and column descriptions as column comments to your destination, making your data more self-documenting and discoverable without additional configuration. Model descriptions are stored as table comments, and column descriptions are stored as column comments in your destination warehouse.
For Databricks, column-level comments are not supported.
Transformations for dbt Core
dbt Core version adoption
We have added support of dbt Core version 1.10.19 and 1.10.20 for the following destinations:
- BigQuery
- ClickHouse Cloud (1.10.19 is only available for now)
- Databricks
- PostgreSQL
- Redshift (1.10.19 is only available for now)
- Snowflake
- Teradata Vantage
Although other destinations support different dbt Core versions, they don't support dbt Core 1.10 due to lack of available dbt adapters for this version.
We have added support of dbt Core version 1.11.6 and 1.11.7 for the following destinations:
- BigQuery
- ClickHouse Cloud (1.11.6 is only available for now)
- Databricks
- PostgreSQL
- Redshift (1.11.6 is only available for now)
- Snowflake
- Teradata Vantage
Although other destinations support different dbt Core versions, they don't support dbt Core 1.11 due to lack of available dbt adapters for this version.
Type Locking
The type locking feature is now in beta. Type locking lets you lock the data types of your connection's columns in the destination.
For more information, see our Type Locking documentation.
New connectors
Smartsheet connector is in beta
The Smartsheet connector is now in beta. For more information, see the Smartsheet connector documentation.
Schema changes
We now automatically remove schemas and tables from the Schema tab in your dashboard if they were deleted from the source. The deletion occurs after a 7-day grace period.
All Fivetran connectors, apart from the ones that do not supply source schema information, support this feature.
ADP Workforce Now
We have added the following new child tables to the WORKER table:
WORKER_PAID_TIME_OFF_ENTRYWORKER_PAID_TIME_OFF_REQUESTWORKER_PAID_TIME_OFF_ACCRUAL_BALANCEWORKER_PAID_TIME_OFF_BALANCE
We are gradually rolling out this change to all existing connections.
BambooHR
We've added a new table, TIME_OFF_REQUEST_DATE. The table contains daily time-off date breakdowns for each time-off request, showing the specific dates and amounts for each day within a request period.
We've added a new table, TIMESHEET_ENTRY. The table contains time tracking records for employees, including clock-in/clock-out entries and hour-based entries, with optional project and task associations.
Braintree
We have added a new column, graphql_id, to the TRANSACTION table. The column contains the unique global identifier for the transaction in Braintree's GraphQL API. We have added the following new columns to the DISPUTE table:
chargeback_protection_levelgraphql_idpre_dispute_program
Braze
We have added a new table, USER_DEVICE, to store device-level information for users. We are gradually rolling out this change to all existing connections.
Chargebee Product Catalog 2.0
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
ENTITLEMENT | |||||
| table | New Table | ENTITLEMENT | |||
SCHEDULED_SUBSCRIPTION_CHANGE | |||||
| table | New Table | SCHEDULED_SUBSCRIPTION_CHANGE | |||
SCHEDULED_SUBSCRIPTION_CHANGE_ITEM_PRICE | |||||
| table | New Table | SCHEDULED_SUBSCRIPTION_CHANGE_ITEM_PRICE | |||
SUBSCRIPTION_ENTITLEMENT | |||||
| table | New Table | SUBSCRIPTION_ENTITLEMENT | |||
Coupa
We have added the following new tables:
QUOTE_REQUEST_ATTACHMENT_RESPONSEQUOTE_REQUEST_ATTACHMENT_RESPONSE_MAPPINGQUOTE_RESPONSEQUOTE_RESPONSE_LINEQUOTE_RESPONSE_LINE_ATTACHMENT_MAPPINGQUOTE_RESPONSE_LINE_EASY_FORM_DATA_MAPPING
We are gradually rolling out this change to all existing connections.
Criteo
Our Criteo connector now supports custom reports. On the connection setup form, you can add campaign statistics custom reports. To learn more, see our Criteo Custom Reports documentation and the Criteo Setup Guide.
We've added the LOG_LEVEL_REPORT table to the Criteo connector, which supports log-level reports. This table provides device-level granular reporting data, enabling you to analyze individual advertising events with detailed information about user interactions, devices, and costs.
e-conomic
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
INVOICE_BOOKED_LINE | |||||
| table | New Table | INVOICE_BOOKED_LINE | |||
JOURNAL_ENTRY | |||||
| table | New Table | JOURNAL_ENTRY | |||
EasyPost
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
PAYMENT_LOG_REPORT | |||||
| column | New Column | shipment_id | |||
SHIPMENT_INVOICE_REPORT | |||||
| column | Rename Column | shipment_report_id 🔑 | shipment_id | ||
Employment Hero
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
PAY_DETAIL | |||||
| column | New Column | currency | |||
| column | New Column | days_per_week | |||
| column | New Column | employee_work_hours | |||
| column | New Column | full_time_equivalent_units | |||
| column | New Column | hours_per_week | |||
| column | New Column | in_review | |||
| column | New Column | zero_hour_based | |||
Facebook Ads
We have added new columns to the CREATIVE_HISTORY table. These columns surface additional fields from the Ad Creative Video Data endpoint.
video_call_to_action_typevideo_image_hashvideo_image_urlvideo_link_descriptionvideo_messagevideo_page_welcome_messagevideo_title
Facebook Pages
We have added the following new tables:
DAILY_PAGE_METRICS_BY_EARNING_SOURCEDAILY_PAGE_METRICS_BY_MONETIZATION_TOOLDAILY_PAGE_MONETIZATION_METRICSDAILY_POST_METRICS_BY_MONETIZATION_TOOLDAILY_POST_MONETIZATION_METRICSLIFETIME_POST_METRICS_BY_MONETIZATION_TOOLLIFETIME_POST_MONETIZATION_METRICS
Fivetran Platform Connector
We've added support for schema, table, and column deletion events. These events are available in the SOURCE_SCHEMA_CHANGE_HISTORY, SOURCE_TABLE_CHANGE_HISTORY, and SOURCE_COLUMN_CHANGE_HISTORY tables of the Fivetran Platform connector and will be attributed the change type DELETE.
Additionally, these events will now be included in the schema change count value displayed in the Status tab on the Connection Details page.
GitHub
We've added the following tables to track auto-merge and merge queue activity on pull requests:
PULL_REQUEST_AUTO_MERGE- this table records when auto-merge is enabled or disabled for a pull request, including the timestamp and who made the change, if any.PULL_REQUEST_MERGE_QUEUE- this table records when a pull request is added to or removed from the merge queue, including the timestamp and who made the change, if any.We've added a new table,
COPILOT_SEAT. The table contains GitHub Copilot seat assignment data per organization, including assignee details, seat plan type, activity timestamps, and the team through which the seat was assigned.
We've added the following new tables to support GitHub Copilot usage metrics at the organization and user levels:
COPILOT_ORG_METRIC— Daily Copilot usage totals for the organization.COPILOT_ORG_METRIC_BY_IDE— Organization Copilot usage broken down by IDE.COPILOT_ORG_METRIC_BY_FEATURE— Organization Copilot usage broken down by feature.COPILOT_ORG_METRIC_BY_LANGUAGE_FEATURE— Organization Copilot usage broken down by programming language and feature.COPILOT_ORG_METRIC_BY_LANGUAGE_MODEL— Organization Copilot usage broken down by programming language and model.COPILOT_ORG_METRIC_BY_MODEL_FEATURE— Organization Copilot usage broken down by model and feature.COPILOT_USER_METRIC— Daily Copilot usage totals per user.COPILOT_USER_METRIC_BY_IDE— Per-user Copilot usage broken down by IDE.COPILOT_USER_METRIC_BY_FEATURE— Per-user Copilot usage broken down by feature.COPILOT_USER_METRIC_BY_LANGUAGE_FEATURE— Per-user Copilot usage broken down by programming language and feature.COPILOT_USER_METRIC_BY_LANGUAGE_MODEL— Per-user Copilot usage broken down by programming language and model.COPILOT_USER_METRIC_BY_MODEL_FEATURE— Per-user Copilot usage broken down by model and feature.
We will discontinue support for the following tables once the underlying GitHub API endpoints are shut down on April 2, 2026:
COPILOT_METRICIDE_CODE_COMPLETION_TOTAL_LANGUAGEIDE_CODE_COMPLETION_EDITORIDE_CODE_COMPLETION_EDITOR_MODELIDE_CODE_COMPLETION_EDITOR_MODEL_LANGUAGEIDE_CHAT_EDITORIDE_CHAT_EDITOR_MODELDOTCOM_CHAT_MODELDOTCOM_PULL_REQUEST_REPOSITORYDOTCOM_PULL_REQUEST_REPOSITORY_MODELCOPILOT_METRIC_TEAMIDE_CODE_COMPLETION_TOTAL_LANGUAGE_TEAMIDE_CODE_COMPLETION_EDITOR_TEAMIDE_CODE_COMPLETION_EDITOR_MODEL_TEAMIDE_CODE_COMPLETION_EDITOR_MODEL_LANGUAGE_TEAMIDE_CHAT_EDITOR_TEAMIDE_CHAT_EDITOR_MODEL_TEAMDOTCOM_CHAT_MODEL_TEAMDOTCOM_PULL_REQUEST_REPOSITORY_TEAMDOTCOM_PULL_REQUEST_REPOSITORY_MODEL_TEAM
We are gradually rolling out this change to all existing connections.
We have added a new column, label, to the ISSUE_LABEL table. We are gradually rolling out this change to all existing connections.
Google Ads
We've added theai_max_setting_enable_ai_max and ai_max_setting_bundling_required columns to the CAMPAIGN_HISTORY table.
We have upgraded our Google Ads connector to version v23.1 of the Google Ads API. Due to the upgrade, we've made the following changes:
- We have added two new columns,
start_date_timeandend_date_time, to theCAMPAIGN_HISTORYtable. These columns replace the existingstart_dateandend_datecolumns, which will no longer be populated. The new columns use a datetime format instead of a date-only format. - The
lead_form_onlycolumn in theDEMAND_GEN_MULTI_ASSET_AD_HISTORYtable will no longer be populated because the field has been removed from the Google Ads API. - The
CALL_AD_HISTORYtable will no longer receive new data because theCallAdtype has been removed from the Google Ads API. Existing historical data in the table is preserved. - We have added the following reporting resources:
DETAIL_CONTENT_SUITABILITY_PLACEMENT_VIEWGROUP_CONTENT_SUITABILITY_PLACEMENT_VIEWMATCHED_LOCATION_INTEREST_VIEW
- We have added the following new fields to the
PER_STORE_VIEWreporting resource:address1address2business_namecitycountry_codephone_numberpostal_codeprovince
Google Display & Video 360
Our Google Display & Video 360 connector can now sync the following metadata:
- channel
- custom_list
- combined_audience
- google_audience
- inventory_source_group
- line_item
- line_item_brand_lift_vendor_config
- line_item_brand_safety_vendor_config
- line_item_creative
- line_item_floodlight_activity_config
- line_item_partner_cost
- line_item_reach_vendor_config
- line_item_related_video
- line_item_video_ad_sequence_step
- line_item_viewability_vendor_config
- line_item_warning_message
- line_item_assigned_targeting_option
- line_item_assigned_combined_audience
- line_item_assigned_custom_list
- line_item_assigned_first_party_and_partner_audience
- line_item_assigned_google_audience
- inventory_source
- inventory_source_creative_config
- inventory_source_accessors_advertiser
- inventory_source_read_advertiser
- inventory_source_read_partner
See the connector's updated ERD for more details.
Google Search Ads 360
We have added new hourly prebuilt report tables:
AD_GROUP_REPORT_HOURLYCAMPAIGN_REPORT_HOURLYCUSTOMER_REPORT_HOURLY
For a full list of prebuilt report tables the connector syncs, see the Google Search Ads 360 ERD.
Guru
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
FOLDER | |||||
| table | New Table | FOLDER | |||
HappyFox
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
CUSTOM_TICKET_CHOICE | |||||
| column | Primary Key Change | custom_ticket_id | custom_ticket_id 🔑 | Added to primary key. | |
| column | Discontinued Column | value_id | |||
TICKET_CATEGORY | |||||
| column | Primary Key Change | ticket_id | ticket_id 🔑 | Added to primary key. | |
TICKET_CUSTOM_FIELD | |||||
| column | Primary Key Change | ticket_id | ticket_id 🔑 | Added to primary key. | |
TICKET_UPDATE | |||||
| column | New Column | message_bcc_list | |||
| column | New Column | message_cc_list | |||
| column | New Column | message_customer_updated | |||
| column | New Column | message_forward_list | |||
| column | New Column | message_html | |||
| column | New Column | message_message_type | |||
| column | New Column | message_subject | |||
| column | New Column | message_text | |||
Intercom
We have renamed the column away_mode_reassigned to away_mode_reassign in the ADMIN table to align with the Intercom API field name.
We have added the following new columns to the CONVERSATION_TAG_HISTORY table:
applied_atapplied_by_idapplied_by_typetag_name
Jira
We've added the following columns to the ATTACHMENT_METADATA table:
content_urlthumbnail_urlfilenameauthor_idcreatedmime_typefile_size
The connector now processes all attachment types from issues, not just ZIP files. For non-ZIP attachments, the table stores standard attachment metadata including download URLs, file information, and author details from the issue's attachment field.
Klaviyo
We have added a new table, ACCOUNT_HISTORY, to store account-level details of Klaviyo accounts for auditing and tracking purposes.
LinkedIn Ad Analytics
We've added the following new columns:
audience_penetrationaverage_dwell_timeaverage_event_watch_timeaverage_event_watch_time_over_15_secondsaverage_event_watch_time_over_2_minutesaverage_event_watch_time_over_30_secondsaverage_video_watch_timecost_per_event_viewcost_per_event_view_over_15_secondscost_per_event_view_over_2_minutescost_per_event_view_over_30_secondscost_per_qualified_leaddocument_completionsdocument_first_quartile_completionsdocument_midpoint_completionsdocument_third_quartile_completionsdownload_clicksevent_viewsevent_views_over_15_secondsevent_views_over_2_minutesevent_views_over_30_secondsevent_watch_timeheadline_clicksheadline_impressionspost_click_job_applicationspost_click_job_apply_clickspost_click_registrationspost_view_job_applicationspost_view_job_apply_clickspost_view_registrationsqualified_leadsreactionsregistrationssubscription_clickstalent_leadsvalid_work_email_leadsvideo_watch_timeviral_document_completionsviral_document_first_quartile_completionsviral_document_midpoint_completionsviral_document_third_quartile_completionsviral_download_clicksviral_job_applicationsviral_job_apply_clicksviral_post_click_job_applicationsviral_post_click_job_apply_clicksviral_post_click_registrationsviral_post_view_job_applicationsviral_post_view_job_apply_clicksviral_post_view_registrationsviral_reactionsviral_registrationsviral_subscription_clicks
to the following following analytics tables:
AD_ANALYTICS_BY_CAMPAIGNAD_ANALYTICS_BY_CREATIVEAD_ANALYTICS_BY_CREATIVE_WITH_CONVERSION_BREAKDOWNMONTHLY_AD_ANALYTICS_BY_MEMBER_COMPANYMONTHLY_AD_ANALYTICS_BY_MEMBER_COMPANY_SIZEMONTHLY_AD_ANALYTICS_BY_MEMBER_COUNTRYMONTHLY_AD_ANALYTICS_BY_MEMBER_INDUSTRYMONTHLY_AD_ANALYTICS_BY_MEMBER_JOB_FUNCTIONMONTHLY_AD_ANALYTICS_BY_MEMBER_JOB_TITLEMONTHLY_AD_ANALYTICS_BY_MEMBER_REGIONMONTHLY_AD_ANALYTICS_BY_MEMBER_SENIORITY
Microsoft Advertising
We have added the following reporting tables:
ASSET_GROUP_PERFORMANCE_DAILY_REPORTASSET_GROUP_PERFORMANCE_HOURLY_REPORT
We are gradually rolling out these changes to all existing connections.
You can populate the new tables with data for free until April 10, 2026. Be sure to exclude the tables that you don't want to count towards paid Monthly Active Rows (MAR) before this date.
We have added the status column to the following tables:
CAMPAIGN_LABEL_HISTORYAD_GROUP_LABEL_HISTORYAD_LABEL_HISTORYKEYWORD_LABEL_HISTORY
The column indicates the association status between the label and the entity, and can have a value of Active or Deleted.
Optimizely
We have added two new columns, feature_key and feature_name, to the EXPERIMENT_HISTORY table.
We have added two new columns, feature_enabled and variable_values, to the EXPERIMENT_VARIATION_HISTORY table.
Paychex
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
COMPANY_CONTACT_TYPE | |||||
| column | Primary Key Change | _fivetran_id 🔑 | _fivetran_id 🔑 | Primary key calculation change. | |
Pipedrive
We have made the following changes to the PRODUCT_DEAL table:
Removed the following columns:
active_flagdiscount_percentagedurationduration_unitquantity_formattedsum_formattedsum_no_discount
Renamed the following columns:
enabled_flagtois_enabledlast_edittoupdate_time
Pylon Support Platform
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
ISSUE | |||||
| column | New Column | team_id | |||
Sage Intacct
We now use the recordno column as the primary key for the PO_DOCUMENT table. Previously, we used the docid column as the primary key.
Salesforce Commerce Cloud
We have added a new column, image_absUrl, to the PRODUCT table.
Samsara
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
AMBIENT_AIR_TEMPERATURE_MILLI_C | |||||
| table | New Table | AMBIENT_AIR_TEMPERATURE_MILLI_C | |||
BAROMETRIC_PRESSURE_PA | |||||
| table | New Table | BAROMETRIC_PRESSURE_PA | |||
DEF_LEVEL_MILLI_PERCENT | |||||
| table | New Table | DEF_LEVEL_MILLI_PERCENT | |||
ECU_SPEED_MPH | |||||
| table | New Table | ECU_SPEED_MPH | |||
ENGINE_COOLANT_TEMPERATURE_MILLI_C | |||||
| table | New Table | ENGINE_COOLANT_TEMPERATURE_MILLI_C | |||
ENGINE_LOAD_PERCENT | |||||
| table | New Table | ENGINE_LOAD_PERCENT | |||
ENGINE_RPM | |||||
| table | New Table | ENGINE_RPM | |||
INTAKE_MANIFOLD_TEMPERATURE_MILLI_C | |||||
| table | New Table | INTAKE_MANIFOLD_TEMPERATURE_MILLI_C | |||
SAP Concur
We have added a new column, external_id, to the ATTENDEE table.
We have added the following new tables:
PAYMENT_REQUESTPAYMENT_REQUEST_DIGESTPAYMENT_REQUEST_LINE_ITEMPAYMENT_REQUEST_LINE_ITEM_ALLOCATIONPAYMENT_REQUEST_LINE_ITEM_MATCHED_PURCHASE_ORDER_RECEIPT
We have added the following new columns to the USER table:
company_idcreated_atdate_of_birthdisplay_nameemployee_numberlast_modified_atmanager_display_namemanager_idnick_namepreference_24_hourpreference_currency_symbol_locationpreference_date_formatpreference_default_cal_viewpreference_distancepreference_end_day_view_hourpreference_first_day_of_weekpreference_hour_minute_separatorpreference_negative_currency_formatpreference_negative_number_formatpreference_number_formatpreference_start_day_view_hourpreferred_languagestart_datetermination_datetimezonetitle
Security Journey
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
ASSIGNMENT | |||||
| column | Primary Key Change | _fivetran_id 🔑 | _fivetran_id 🔑 | Primary key calculation change. | |
| column | Discontinued Column | first_name | |||
| column | Discontinued Column | last_name | |||
| column | Discontinued Column | passed | |||
| column | Discontinued Column | progress | |||
| column | Discontinued Column | total | |||
| column | New Column | passed_lessons | |||
| column | New Column | path_name | |||
| column | New Column | total_lessons | |||
ENROLLMENT | |||||
| column | Discontinued Column | alls | |||
| column | Discontinued Column | archived | |||
| column | Discontinued Column | deleted_at | |||
| column | Discontinued Column | first_name | |||
| column | Discontinued Column | id 🔑 | No longer a primary key. | ||
| column | Discontinued Column | last_engagement | |||
| column | Discontinued Column | last_name | |||
| column | Discontinued Column | passed | |||
| column | Discontinued Column | progress | |||
| column | Discontinued Column | progress_percent | |||
| column | Discontinued Column | public_id | |||
| column | Discontinued Column | required | |||
| column | Discontinued Column | required_passed | |||
| column | Discontinued Column | required_progress_percent | |||
| column | Discontinued Column | required_total | |||
| column | Discontinued Column | role_name | |||
| column | Discontinued Column | started_at | |||
| column | Discontinued Column | time_spent | |||
| column | Discontinued Column | total | |||
| column | Discontinued Column | user_id | |||
| column | Primary Key Change | _fivetran_id 🔑 | New primary key. | ||
| column | New Column | level_type | |||
| column | New Column | path_enrollment_completed_at | |||
| column | New Column | path_enrollment_created_at | |||
| column | New Column | path_enrollment_name | |||
| column | New Column | path_enrollment_status | |||
| column | New Column | path_enrollment_updated_at | |||
| column | New Column | points_earned | |||
LESSON_ATTEMPT | |||||
| column | Primary Key Change | _fivetran_id 🔑 | _fivetran_id 🔑 | Primary key calculation change. | |
| column | Discontinued Column | assessments | |||
| column | Discontinued Column | created | |||
| column | Discontinued Column | experiment_passed | |||
| column | Discontinued Column | first_name | |||
| column | Discontinued Column | last_name | |||
| column | Discontinued Column | last_updated | |||
| column | Discontinued Column | module_name | |||
| column | Discontinued Column | user_id | |||
| column | New Column | completed_at | |||
| column | New Column | created_at | |||
| column | New Column | difficulty | |||
| column | New Column | length | |||
| column | New Column | lesson_name | |||
| column | New Column | questions | |||
| column | New Column | started_at | |||
| column | New Column | updated_at | |||
USERS | |||||
| column | Discontinued Column | ad_id | |||
| column | Discontinued Column | business_unit_description | |||
| column | Discontinued Column | country | |||
| column | Discontinued Column | deleted_at | |||
| column | Discontinued Column | department_number | |||
| column | Discontinued Column | employee_number | |||
| column | Discontinued Column | employee_secondary_number | |||
| column | Discontinued Column | initial | |||
| column | Discontinued Column | managers_employee_number | |||
| column | Discontinued Column | managers_name | |||
| column | Discontinued Column | phone_number | |||
| column | New Column | archived | |||
| column | New Column | archived_at | |||
Shopify
We have added the following new columns to the CUSTOMER table:
default_phone_numberdefault_phone_number_marketing_collected_fromdefault_phone_number_marketing_opt_in_leveldefault_phone_number_marketing_statedefault_phone_number_marketing_updated_atdefault_phone_number_source_location_idsms_marketing_consent_collected_fromsms_marketing_consent_opt_in_levelsms_marketing_consent_statesms_marketing_consent_updated_at
We have added the following new columns to the TRANSACTION table:
payment_credit_card_namepayment_credit_card_walletpayment_credit_card_expiration_monthpayment_credit_card_expiration_yearpayment_id.
We have added a new column, total_outstanding, to the ORDER table.
We have added two new columns, delivery_method_presented_name and delivery_method_service_code, to the FULFILLMENT_ORDER table. These columns represent the delivery option name shown to the buyer at checkout and the shipping method reference code, respectively, sourced from the nested DeliveryMethod object in Shopify's GraphQL API.
Snapchat Ads
We've added two new columns, measured_impressions and viewable_impressions, to the following prebuilt report tables:
AD_DAILY_REPORTAD_HOURLY_REPORTAD_SQUAD_DAILY_REPORTAD_SQUAD_HOURLY_REPORTCAMPAIGN_DAILY_REPORTCAMPAIGN_HOURLY_REPORT
These viewability metrics indicate how many ad impressions were measured for viewability and how many met the viewability threshold.
These columns are not available in dimensional report tables, such as geo, device, or demographic breakdowns.
SonarQube
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
ISSUE_FLOW_LOCATION | |||||
| column | Discontinued Column | _fivetran_id 🔑 | |||
| column | Primary Key Change | index 🔑 | Added to primary key. | ||
Spotify Ads
We have added the delivery_goal column to the AD_SET table and the delivery_goal_group column to the CAMPAIGN table.
Square
We have added a new column, ticket_name, to the ORDER table.
We have added a new table, CATALOG_ITEM_CATEGORY. You can use this table to join the CATALOG_ITEM and CATALOG_CATEGORY tables, since the category_id column in CATALOG_ITEM is now discontinued. We are gradually rolling out this change to all existing connections.
We have added two new columns, reporting_category_id and reporting_category_ordinal, to the CATALOG_ITEM table.
Stripe
We have added a new column, tax_behavior, to the PRICE table.
We have added a new column, next_invoice_sequence, to the CUSTOMER table.
We have added two new columns, trace_id_status and trace_id_value, to the PAYOUT table.
We have added following new columns to the CHARGE table:
amount_capturedfailure_balance_transaction_idstatement_descriptor_suffix
We have added two new columns, automatic_tax_enabled and automatic_tax_liability_type, to the SUBSCRIPTION_HISTORY table.
The Trade Desk
We have added the following new tables:
AD_GROUPCREATIVE
These tables contain metadata about your ad groups and creatives, respectively. We are gradually rolling out this change to all existing connections.
TikTok Ads
We have added a new column, campaign_automation_type, to the CAMPAIGN_HISTORY table. The column indicates the campaign automation type and can take the following values: MANUAL, SMART_PLUS, or UPGRADED_SMART_PLUS.
Vitally
| Table/column | Change type | Old name | New name | Notes | |
|---|---|---|---|---|---|
CONVERSATION_MESSAGE_CC | |||||
| column | Primary Key Change | id 🔑 | id | No longer a primary key. | |
| column | Primary Key Change | index 🔑 | New primary key. | ||
CONVERSATION_MESSAGE_TO | |||||
| column | Primary Key Change | id 🔑 | id | No longer a primary key. | |
| column | Primary Key Change | index 🔑 | New primary key. | ||
PROJECT | |||||
| table | New Table | PROJECT | |||
Workday Financial Management
We have added a new column, descriptor, to the WORKTAG table.
We have fixed foreign key references in the ACCOUNT_POSTING_RULE and ACCOUNT_POSTING_RULE_CONDITION tables. These tables now correctly reference the ledger_account_code field instead of the ledger_account_id field when establishing foreign key relationships to the LEDGER_ACCOUNT table.
This change improves data integrity by ensuring foreign keys point to the actual primary key field (ledger_account_code) of the LEDGER_ACCOUNT table.
Workday HCM
We have added a new table, COMPENSATION_STEP.
We have added a new column, requisition_role_code, to the JOB_REQUISITION_ROLE_ASSIGNMENT table.
Xero
We have added a new column, merged_to_contact_id, to the CONTACT table.
Improvements
Amazon S3
We now support specifying custom primary keys for tables created through dynamic table mapping.
Amazon Selling Partner
We now skip reports that return an HTTP 403 Forbidden error due to insufficient Amazon Selling Partner account permissions and log a warning instead of failing the sync. To address these warnings, ensure your account has the required permissions for the affected reports.
Azure Blob Storage
We now support specifying custom primary keys for tables created through dynamic table mapping.
Bazaarvoice
We have updated the sync strategy for the REVIEW table and its child tables. In addition to the incremental syncs that capture new records and updates, we now perform a weekly re-import to capture updates and deletes.
BigQuery destination
BigQuery destinations now support NaN and Infinity values for DOUBLE and FLOAT data types. Previously, we stored these values as NULL. Be sure to re-sync your connections to backfill existing records with NaN and Infinity values.
Churnkey
We have implemented pagination for the SESSION table.
CockroachDB
We now support tables with hash-sharded primary keys and tables with virtual columns in the primary key.
Criteo
We have upgraded our Criteo connector from version 2025.04 to 2026.01 of the Criteo API. Learn more in the Criteo API v2026.01 Release Notes. We're gradually rolling this change out to all existing connections.
Dropbox
Our Dropbox connector now supports syncing files within nested folders, in Magic Folder mode. To support this enhancement, we have added a new toggle, Include subfolders, in the connection setup form. For more information, see our setup instructions. We are gradually rolling out this enhancement to all existing connections.
Gainsight Customer Success
Our Gainsight Customer Success connector now supports OAuth 2.O authentication. To support this enhancement, we have made the following changes:
- Added a new field, Authentication, to the connection setup form, allowing you to choose between OAuth 2.0 and API key authentication methods
- Added a new parameter,
authentication_method, to the Fivetran REST API
For more information, see our setup instructions.
Google Ads
To stay within Google Ads API rate limits, account structure tables (campaigns, ad groups, ads, and similar) are refreshed at most once every 12 hours per account.
Google Cloud Storage
We now support specifying custom primary keys for tables created through dynamic table mapping.
Google Display & Video 360
We have added the ability to split reports by advertiser in multi-report mode. When enabled, reports are queried separately for each selected advertiser. Use this option when reporting API fails or times out on report generation due to large data volumes across multiple advertisers.
Google Drive
Our Google Drive connector now supports syncing files within nested folders, in Magic Folder mode. To support this enhancement, we have added a new toggle, Include subfolders, in the connection setup form. For more information, see our setup instructions. We are gradually rolling out this enhancement to all existing connections.
Google Search Ads 360
We have updated our Google Search Ads 360 connector to support the Search Ads Reporting API version v0 (2026-03-10).
We've added support for the following fields for custom reports:
ad_group.final_url_suffixad_group.tracking_url_templatead_group_ad.ad.final_app_urlsad_group_ad.ad.final_mobile_urlsad_group_ad.ad.final_url_suffixad_group_ad.ad.tracking_url_templatead_group_criterion.final_mobile_urlsad_group_criterion.url_custom_parametersasset.final_mobile_urlsasset.final_url_suffixasset.url_custom_parameterscampaign.feed_types
We've added support for the following metrics for custom reports:
metrics.average_cart_sizemetrics.average_impression_frequency_per_usermetrics.average_order_value_microsmetrics.cost_of_goods_sold_microsmetrics.gross_profit_marginmetrics.gross_profit_microsmetrics.ordersmetrics.revenue_microsmetrics.unique_usersmetrics.units_sold
We've added support for the following segments for custom reports:
segments.ad_format_typesegments.geo_target_postal_codesegments.vertical_ads_event_participant_display_namessegments.vertical_ads_hotel_classsegments.vertical_ads_listing_brandsegments.vertical_ads_listing_citysegments.vertical_ads_listing_countrysegments.vertical_ads_listing_regionsegments.vertical_ads_listingsegments.vertical_ads_partner_account
HighLevel
We no longer support multiple location IDs for our HighLevel connector.
HubSpot
We have simplified how the HubSpot connector handles merged records to prevent duplicate data. When you merge records in HubSpot, Fivetran now marks the merged records as deleted (_fivetran_deleted = true). This change enables you to filter out inactive records without using complex joins.
We now support HubSpot's Services API to sync service records from your HubSpot account. To support this enhancement, we have added the following new tables:
SERVICESERVICE_COMPANYSERVICE_CONTACTSERVICE_DEALSERVICE_ENGAGEMENTSERVICE_PIPELINESERVICE_PIPELINE_STAGESERVICE_PROPERTY_HISTORYSERVICE_TICKET
We are gradually rolling out this enhancement to all existing connections.
We have added a new table, DEAL_SPLIT, using HubSpot's Deal Splits API to sync deal split information from your HubSpot account.
Intercom
The Intercom connector now supports table re-syncs.
Klaviyo
You can now configure a rollback window of 2–90 days for custom reports in Klaviyo connections.
For more information, see our setup guide.
Looker
We have renamed the Subdomain field in the connection setup form to Domain.
MongoDB
We no longer support MongoDB server versions earlier than 4.0. If you have an existing connection to a MongoDB server running version 3.x or earlier, syncs will no longer work. To continue syncing, upgrade your MongoDB server to version 4.0 or later.
NetSuite SuiteAnalytics
History mode for the NetSuite SuiteAnalytics connector is now generally available.
Oracle
We have made the following improvements to the Binary Log Reader incremental sync method for our Oracle connector:
We now support Oracle database versions from 11g R2 and above. Previously, we supported only Oracle 12c and 19c versions.
We now support the Binary Log Reader method for our Oracle RAC connector.
Pinterest Ads
We've removed the engagement_attribution_window configuration option from the Pinterest Ads connector setup form as it's no longer supported by Pinterest. For more details, see Pinterest changelogs.
Pipedrive
We now sync string values exactly as returned by the Pipedrive API, without performing HTML decoding, for the following tables:
ACTIVITYACTIVITY_PERSONDEAL_HISTORYORGANIZATIONPERSONPIPELINEPRODUCTPRODUCT_PRICESTAGE
PostgreSQL
We now support PostgreSQL version 18. For more information, see our PostgreSQL documentation.
Sailthru
We have added a new Campaign query lookback window in days option to the Sailthru connector. This allows you to configure the lookback window between 2 and 90 days for the CAMPAIGN_QUERY table during incremental syncs. Previously, we fetched the last 60 days of campaign query data during each incremental sync. For more information, see our documentation.
Salesforce
We have added the API Usage Limit field to our Salesforce connection setup form to support configurable API usage limits. You can now set a custom API usage threshold based on your Salesforce edition and requirements.
This change is applicable to all Salesforce connections.
We now support implicit currency conversion in our formula field translations for Salesforce. For more information, see our documentation.
We are gradually rolling out this enhancement to all existing connections.
Samsara
The Samsara connector now supports priority-first sync. Priority-first syncs fetch your most recent data first so that it's quickly ready for you to use. Samsara's priority-first syncs fetch the most recent 30 days' worth of data from the following tables:
AGENT_SAMBIENT_AIR_TEMPERATURE_MILLI_CTATEBAROMETRIC_PRESSURE_PADEF_LEVEL_MILLI_PERCENTECU_SPEED_MPHENGINE_COOLANT_TEMPERATURE_MILLI_CENGINE_LOAD_PERCENTENGINE_RPMINTAKE_MANIFOLD_TEMPERATURE_MILLI_C
To learn more, see our priority-first sync documentation.
SAP ERP on HANA
A new version of the Fivetran NetWeaver API is now available for download: v1900309.
Improvements in Fivetran NetWeaver API v1900309:
- We improved the performance of the
/FIVETRAN/TRIGGERStransaction to avoid out-of-memory issues when displaying or cleaning data for large shadow tables. - We improved handling of DDL changes in source and shadow tables.
- You can now use SAP Message Server to connect to SAP landscapes with multiple application server instances, leveraging SAP's built-in load balancing and automatic failover to healthy instances. For more information, see the relevant section in our SAP ERP on HANA Setup Guide.
- You can now route connections through SAP Router, an application-layer proxy that controls RFC traffic between external systems and your SAP landscape. For more information, see the relevant section in our SAP ERP on HANA Setup Guide.
SFTP
We now support specifying custom primary keys for tables created through dynamic table mapping.
Our SFTP connector now supports syncing files within nested folders, in Magic Folder mode. To support this enhancement, we have added a new toggle, Include subfolders, in the connection setup form. For more information, see our setup instructions. We are gradually rolling out this enhancement to all existing connections.
SharePoint
Our SharePoint connector now supports syncing files within nested folders, in Magic Folder mode. To support this enhancement, we have added a new toggle, Include subfolders, in the connection setup form. For more information, see our setup instructions. We are gradually rolling out this enhancement to all existing connections.
Slack
We have added a new drop-down menu, App Level, to the connection setup form. You can now specify the slack app level from which you want to sync the data. We have also added a new config parameter, app_level, to the Fivetran REST API.
Snowflake destination
Snowflake destinations now support NaN and Infinity values for DOUBLE and FLOAT data types. Previously, we stored these values as NULL. Be sure to re-sync your connections to backfill existing records with NaN and Infinity values.
The Default Virtual Warehouse drop-down menu in the destination setup form is now a mandatory field. You must select a virtual warehouse when configuring your Snowflake destination.
Splunk
You can now set a rollback window between 0 and 7 days for your Splunk connections. The default is 2 days. Learn more in our rollback sync documentation.
Zendesk Support
We now support Unstructured File Replication for our Zendesk connector. To support this enhancement, we have added a new toggle, Sync Zendesk files to your destination's object storage, to the connection setup form. For more information, see our setup instructions. We are gradually out this enhancement to all existing connections.