
PostgreSQL Setup Guide
Follow these instructions to replicate your PostgreSQL database to your destination using Fivetran. This guide applies to self-hosted PostgreSQL, Amazon Aurora PostgreSQL, Amazon RDS for PostgreSQL, Azure Database for PostgreSQL, Google Cloud SQL for PostgreSQL, Heroku Postgres, and PostgreSQL-compatible databases such as Neon and Supabase.
When a step contains provider-specific instructions, follow the instructions for your PostgreSQL service. Otherwise, follow the common instructions.
More information about the setup form in the Fivetran dashboard
The Fivetran connection setup form is organized into the following tabs: Prerequisites, Connection name, Networking or Hybrid Deployment, Database access, and Incremental sync. In each tab, you need to specify the required parameters to complete the connection configuration successfully. This involves performing the following actions:
Depending on how your destination is configured, the setup form displays either the Networking or Hybrid Deployment tab. If your destination is configured for Hybrid Deployment, the Hybrid Deployment tab is displayed instead of the Networking tab.
In the Networking tab, specify the networking information required to establish the connection between your database and Fivetran. For this, you may need to configure certain networking settings based on the connection method you select. You must have network administrative access or assistance from a network administrator to configure these settings.
In the Hybrid Deployment tab, you can select the Hybrid Deployment Agent.
In the Database access tab, specify the database connection parameters. For this, you may need to create a database user and grant the necessary permissions. You must have database administrative access or assistance from a database administrator to configure these settings.
In the Incremental sync tab, select the incremental sync method. For this, you may need to configure certain database settings based on the incremental sync method you select. You must have database administrative access or assistance from a database administrator to configure these settings.
The Add collaborator button lets you invite a network or database administrator to assist in configuring and providing the necessary information. A collaborator can view and edit a connection's configuration.
The Save for Later button lets you save the information you've entered so far, enabling you to exit the screen and return later to resume the setup process. This feature is helpful if you need to pause to gather additional information or finalize the setup at a later time.
Setup instructions
Prerequisites
Before setting up your connection, ensure you have the following information and access rights to connect your PostgreSQL database to Fivetran.
Networking requirements:
- Network administrative access (to configure firewall rules or security groups to allow Fivetran IP addresses)
- Access to the host machine
- TLS enabled on your database
- Additional requirements depending on the connection method you choose (for example, SSH, Private Link, Proxy Agent)
- (For Supabase with logical replication) IPv4 add-on
Database requirements:
- PostgreSQL version 10 - 18
Amazon Aurora PostgreSQL requires version 11 - 18. Aurora Serverless v2 requires PostgreSQL version 13 or later.
- Access to the database server
- Database administrative access (to provision a database user for Fivetran)
- For Amazon RDS or Aurora, an AWS account with permission to manage parameter groups, security groups, and network ACLs
Heroku Postgres does not support logical replication for Fivetran connections. Select Query-Based as the incremental sync method. Contact Heroku Support if you require logical replication support.
(Optional, Private Preview only) To manage credentials outside of Fivetran, you need an External Secret Manager configured for your account before starting setup.
Click Next to proceed to the Connection name tab.
Connection name
In the Destination schema prefix field, enter a name for the connection. This name is prefixed to each replicated schema on the destination and cannot be changed once your connection is created.
To invite collaborators (for example, network/database administrator), you must save the connection name first.
In the Destination names field, choose the naming convention you want Fivetran to use for the schemas, tables, and columns in your destination:
- Source naming: Preserves the original schema, table, and column names from the source system in your destination, and ignores the Destination schema prefix specified in the setup form. However, when multiple connections share the same source schema name (for example,
public), Fivetran stores their tables in the same destination schema. Tables with duplicate names may lead to overwrites and data inconsistencies. Be sure to use unique table names across connections that write to the same schema. - Fivetran naming: Standardizes the schema, table, and column names in your destination according to the Fivetran naming conventions.
If you want to modify your selection, make sure you do it before you start the initial sync.
Depending on your selection, we will either prefix the connection name to each replicated schema or use the source schema names instead.
- Source naming: Preserves the original schema, table, and column names from the source system in your destination, and ignores the Destination schema prefix specified in the setup form. However, when multiple connections share the same source schema name (for example,
Click Save and continue to proceed to the Networking or Hybrid Deployment tab.
Networking or Hybrid Deployment
Depending on how your destination is configured, the setup form displays either the Networking or Hybrid Deployment tab. The Hybrid Deployment tab is displayed only if your destination is configured for Hybrid Deployment; otherwise, the Networking tab is displayed in its place.
Expand the section below that applies to your setup and follow the instructions.
Networking
Expand for instructions
Specify the networking-related information required to establish the connection between your database server and Fivetran. You may need to configure certain networking settings based on the connection method you select. You must have network administrative access or assistance from a network administrator to configure these settings.
Choose and configure the connection method
Decide on the connection method you want to use to connect Fivetran to your database, and set up the required network configurations. The connection methods are:
Connect directly
Connect directly
Fivetran connects directly to your PostgreSQL database. This is the simplest connection method to set up, requiring minimal configuration.
To connect directly, you must do the following:
Enable TLS on your PostgreSQL database. Follow the instructions for your PostgreSQL service:
- PostgreSQL
- Amazon RDS for PostgreSQL and Amazon Aurora PostgreSQL
- Azure Database for PostgreSQL
- Google Cloud SQL for PostgreSQL
For managed PostgreSQL-compatible services such as Neon, Supabase, and Heroku Postgres, TLS is managed by the service.
Configure your firewall and/or other access control systems to allow incoming connections to your PostgreSQL host and port (usually
5432) from Fivetran IPs for your database's region.
After completing the steps above, some platforms require additional configuration:
If you are connecting to Supabase, use the direct connection method with the IPv4 add-on, or query-based replication with the session pooler.
Connect using SSH
Connect using SSH
Fivetran connects to a separate server in your network that provides an SSH tunnel to your PostgreSQL database. You must connect through SSH if your database resides in an inaccessible network.
To connect using an SSH tunnel, configure an SSH tunnel between Fivetran and your PostgreSQL database. For more information, see our SSH connection setup documentation.
The SSH tunnel setup requires adding Fivetran's SSH public key to the authorized_keys file on your SSH tunnel host. Copy the public key from the connector setup form, which is visible when you select Connect via an SSH tunnel in the Connection method drop-down.
Connect using private networking
Connect using private networking
Private networking enables communication between private networks and services without exposing traffic to the public internet. Private networking is the most secure connection method.
You must have a Business Critical plan to use private networking.
We support the following providers:
- AWS PrivateLink – used for VPCs and AWS-hosted or on-premises services. For more information, see our AWS PrivateLink setup documentation.
- Azure Private Link – used for Virtual Networks (VNets) and Azure-hosted or on-premises services. For more information, see our Azure PrivateLink setup documentation.
- Google Cloud Private Service Connect – used for VPCs and Google-hosted or on-premises services. For more information, see our Google Cloud Private Service Connect setup documentation.
Connect using Proxy Agent
Connect using Proxy Agent
Fivetran connects to your database through the Proxy Agent, providing secure communication between Fivetran processes and your database host. The Proxy Agent is installed in your network and creates an outbound network connection to the Fivetran-managed SaaS.
To learn more about the Proxy Agent, how to install it, and how to configure it, see our Proxy Agent documentation.
Configure provider network access
Follow the instructions for your PostgreSQL service:
Amazon RDS for PostgreSQL or Amazon Aurora PostgreSQL
In the Amazon RDS dashboard, select the database instance that Fivetran will connect to.
In Connectivity & security, make a note of the endpoint and port. For a direct connection, ensure Public accessibility is enabled.
Open the linked VPC security group and edit its inbound rules.
Add a custom TCP rule for the database port (usually
5432). For a direct connection, set the source to Fivetran IPs for your database's region. For an SSH tunnel, set the source to{your-ssh-tunnel-server-ip-address}/32.If your database instance is in a VPC, configure network ACLs:
Configure network ACLs (VPC only)
Return to the RDS dashboard.
Click on your database instance.
Click the link to the instance's VPC.
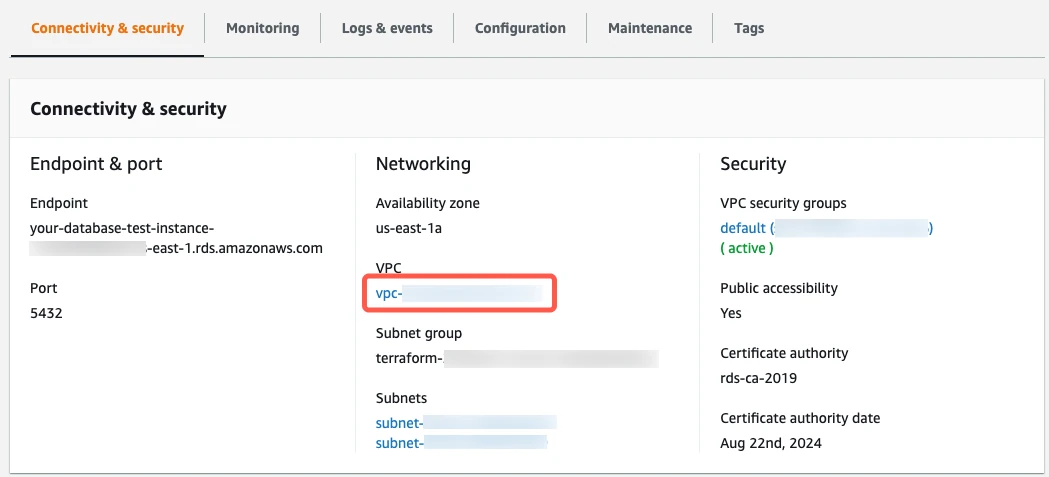
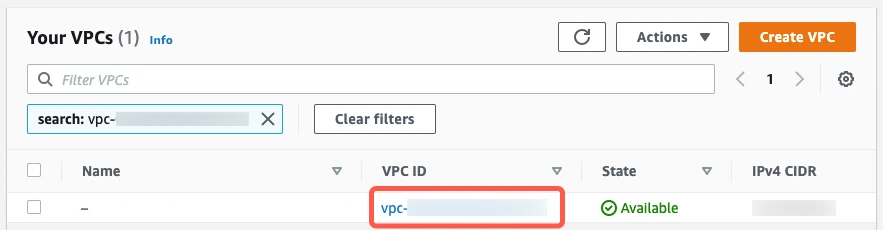
Click the VPC ID.
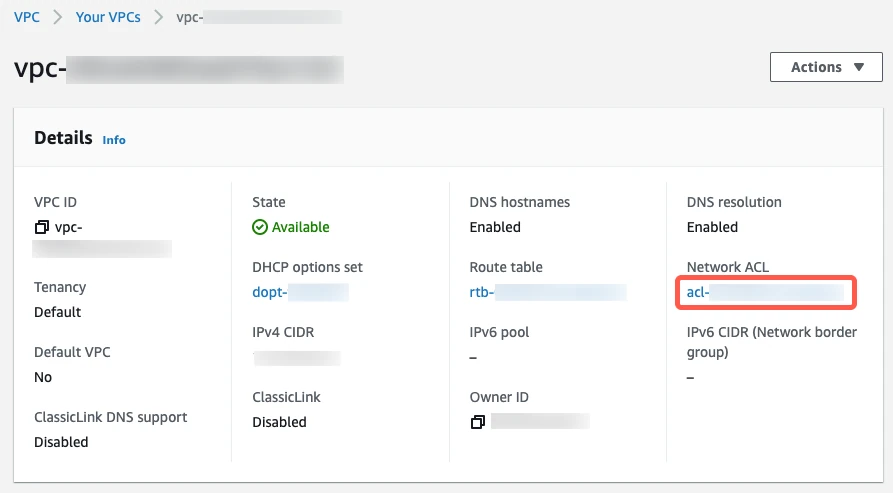
In the Details section, click on the Network ACL.
Click the Network ACL ID.
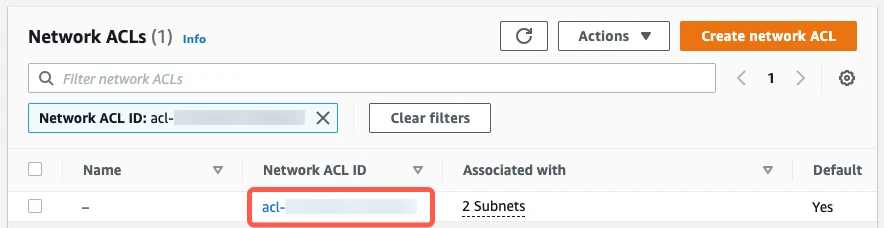
You will see tabs for Inbound Rules and Outbound Rules. You must edit both.
Edit inbound rules
Select Inbound Rules.
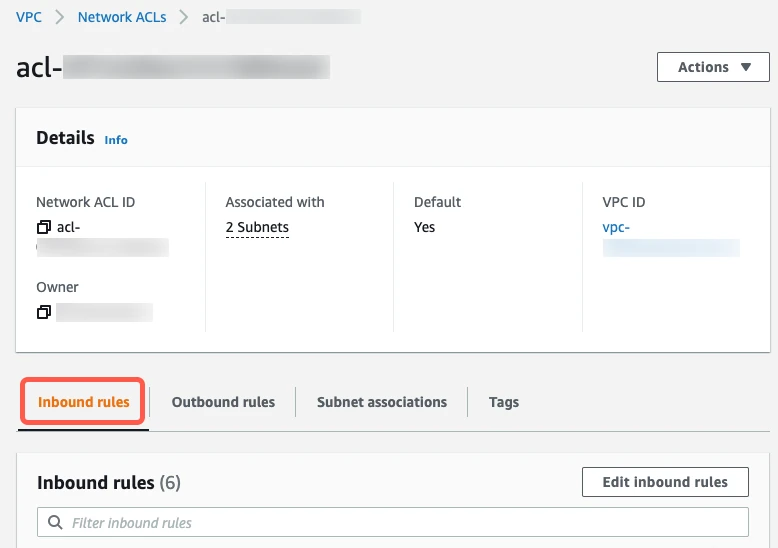
If you have a default VPC that was automatically created by AWS, the settings already allow all incoming traffic. To verify that the settings allow incoming traffic, confirm that the Source value is
0.0.0.0/0and that the ALLOW entry is listed above the DENY entry.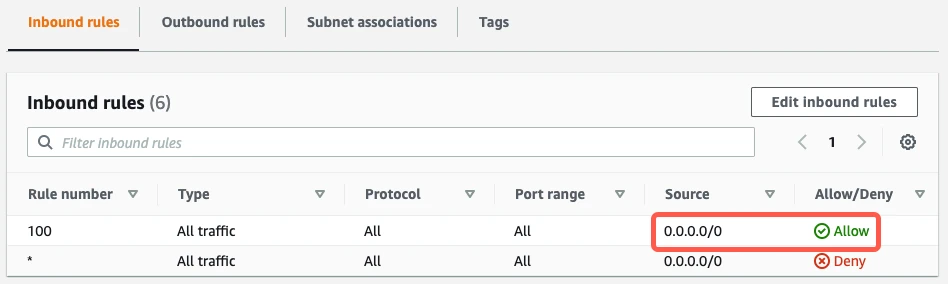
If your inbound rules don't include an
ALL - 0.0.0.0/0 - ALLOWentry, edit the rules to allow the Source to access the port number of your database instance. (The port will be5432for direct connections, unless you changed the default.) For additional help, see Amazon's Network ACL documentation.- If you're connecting directly, enter Fivetran's IPs for your database's region.
- If you're connecting using an SSH tunnel, enter
{your-ssh-tunnel-server-ip-address}/32.
Edit outbound rules
Select Outbound Rules.
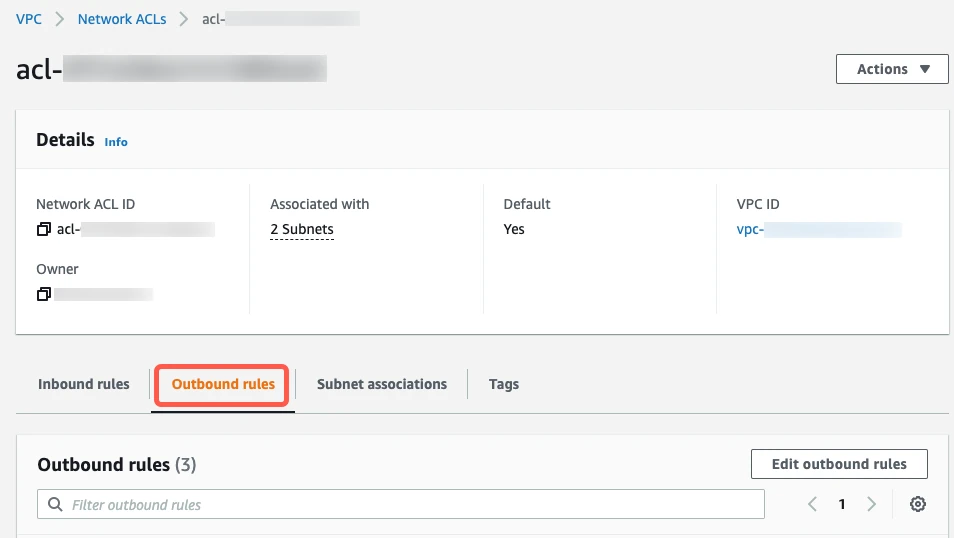
If your outbound rules don't include an
ALL - 0.0.0.0/0 - ALLOWentry, edit the rules to allow outbound traffic to all ports1024-65535fordestination 0.0.0.0/0. For additional help, see AWS's Network ACLs documentation.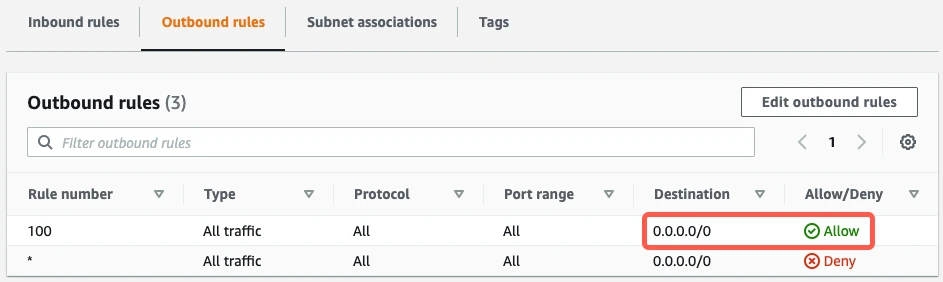
Azure Database for PostgreSQL: For a direct connection, open the server's Networking settings in the Azure portal and add firewall rules for Fivetran IPs for your database's region.
Google Cloud SQL for PostgreSQL: Grant Fivetran's data processing servers access to your database.
These steps apply to direct connections and SSH tunnels that connect to the instance's public IP address. If you use the Cloud SQL Auth Proxy, you do not need to configure authorized networks.
In your Google Cloud Platform SQL dashboard, click on your primary database or read replica.
In the left menu, go to the Connections tab, then the Networking tab.
Ensure that Public IP is enabled. In the Authorized networks section, expand New IP range.
In the Name field, enter a name for Fivetran. What you enter in the IP range field depends on whether you're connecting directly or using an SSH tunnel.
- If you're connecting directly, enter Fivetran's IPs for your database's region.
- If you're connecting using an SSH tunnel, enter
{your-ssh-tunnel-server-ip-address}/32, using the public IPv4 address from which your SSH server connects to Cloud SQL.
Click Done, then Save. Wait for the database to be updated with the new settings.
In the left menu, go to the Overview tab.
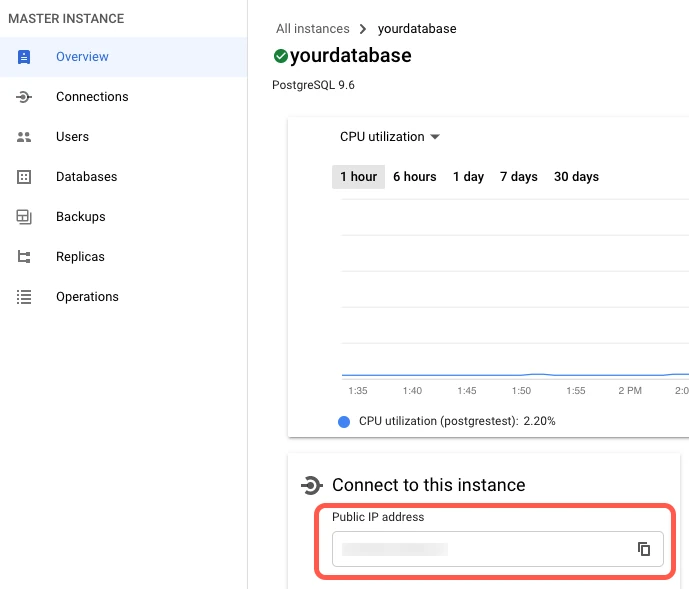
In the Connect to this instance section, find your database's public IP address and make a note of it. You'll need it for the Host field in the Networking tab of the Fivetran setup form.
Heroku Postgres: Go to your Heroku app's Add-ons page, open the PostgreSQL database, and record the Host and Port from Connection Settings.
Specify Networking parameters
In the Fivetran setup form's Networking tab,
Select your Connection method.
Provide the details required for your selected Connection method.
Connect Directly
- Copy the Fivetran IP addresses (or CIDR) that you must safelist in your firewall.
- In the Host field, enter your database host's IP (for example,
1.2.3.4) or domain (for example,your.server.com). For Google Cloud SQL for PostgreSQL, enter the public IP address of the instance you want Fivetran to connect to. If you created a read replica, enter the replica's public IP address. - In the Port field, enter your database instance's port number (usually
5432).
Connect via SSH Tunnel
- In the SSH Host field, enter the hostname of your SSH server (do not use a load balancer's IP address or hostname).
- In the SSH Port field, enter the port number for the SSH connection.
- In the SSH User field, enter the username for the SSH connection.
- The Require TLS through Tunnel toggle is ON by default. Keep it ON if you enabled TLS on your database in the Choose and configure the connection method step above.
- Copy the Fivetran IP addresses (or CIDR) that you must safelist in your firewall.
- In the Host field, enter your database host's IP (for example,
1.2.3.4) or domain (for example,your.server.com). - In the Port field, enter your database instance's port number (usually
5432).Ensure that you have added the Fivetran SSH Public Key to the
authorized_keysfile on your SSH tunnel host.Google Cloud SQL for PostgreSQL: If you are connecting through a Cloud SQL Auth Proxy, use
127.0.0.1as the Host and the external IP address or hostname of the server running the Cloud SQL Auth Proxy as the SSH Host. Turn the Require TLS through Tunnel toggle OFF — the Cloud SQL Auth Proxy handles TLS encryption transparently, so Fivetran connects to it without TLS.
Connect via Private Networking
- Select an existing private networking connection from the drop-down menu or click Configure a new connection to create and use a new connection.
- If you enabled TLS on your database in the Choose and configure the connection method step above, keep the Require TLS when using Private Networking toggle turned ON.
- Copy the Fivetran IP addresses (or CIDR) that you must safelist in your firewall.
- In the Port field, enter your database instance's port number (usually
5432).
Connect via Proxy Agent
- Select an existing agent from the Proxy agents drop-down list or click + Configure a new proxy agent to set up a new agent.
- If you enabled TLS on your database in the Choose and configure the connection method step above, keep the Require TLS when using Proxy Agent toggle turned ON.
- Copy the Fivetran IP addresses (or CIDR) that you must safelist in your firewall.
- In the Host field, enter your database host's IP (for example,
1.2.3.4) or domain (for example,your.server.com). - In the Port field, enter your database instance's port number (usually
5432).
Click Next to proceed to the Database access tab.
Hybrid Deployment
Expand for instructions
Specify Hybrid Deployment connection parameters
In the Fivetran setup form's Hybrid Deployment tab,
- The Hybrid Deployment Agent associated with your destination is pre-selected. To use a different agent, click Replace agent, and then select the agent of your choice.
- In the Host field, enter your database host's IP (for example,
1.2.3.4) or domain (for example,your.server.com). - In the Port field, enter your database instance's port number (usually
5432). - Click Next to proceed to the Database access tab.
Create a read replica (optional)
A read replica reduces the load that Fivetran places on your primary database. To use logical replication from a PostgreSQL standby, Amazon RDS read replica, Azure read replica, or Google Cloud SQL read replica, use PostgreSQL 16 or later. Otherwise, use Query-Based replication.
Amazon RDS for PostgreSQL
- In the Amazon RDS dashboard, select your PostgreSQL instance, then select Actions > Create read replica.
- Enter a unique DB instance identifier and choose an appropriate DB instance class.
- Make the replica publicly accessible only when connecting directly. Keep it private for SSH, AWS PrivateLink, Proxy Agent, or Hybrid Deployment connections.
- Attach a parameter group that sets
max_standby_streaming_delayto 15–30 minutes (900000–1800000ms). - Create the replica and wait until its status is
available.
Amazon Aurora PostgreSQL
Aurora readers support Query-Based replication only; logical replication must connect to the primary writer.
- In the Amazon RDS dashboard, select the Aurora cluster, then select Actions > Add reader.
- Enter a DB instance identifier, choose an instance class, and select the cluster parameter group.
- Make the reader publicly accessible only when connecting directly.
- Add the reader and wait until its status is
available. - Set
max_standby_streaming_delayto 15–30 minutes.
Google Cloud SQL for PostgreSQL
- In the Google Cloud SQL dashboard, select your primary database and go to the Replicas tab.
- Click Create Read Replica and enter an instance ID.
- Click Done, then click Create and wait for the replica to become available.
- Open the replica's Overview tab and record its public IP address for the Host field in Fivetran.
If queries on a replica are canceled, see Resolve "Canceling Statement Due to Conflict With Recovery" Error.
Configure client certificate (optional)
Google Cloud SQL for PostgreSQL and Heroku Private or Shield instances support client certificate authentication when connecting directly or through private networking.
Google Cloud SQL for PostgreSQL
Configure the client certificate on the Cloud SQL instance that Fivetran will connect to. If you created a read replica, configure the certificate on the replica, not the primary instance. Complete these steps in the Google Cloud console before proceeding to the Database access tab in the Fivetran setup form.
- Create a client certificate by following the instructions in the Google Cloud SQL documentation.
- Download the
client-key.pemandclient-cert.pemfiles to a secure location. You need them in the Database access tab if you select the Client certificate authentication method.The
client-key.pemandclient-cert.pemfiles are only available to download during client certificate creation. - In the left menu of your Google Cloud SQL dashboard, go to the Connections tab.
- Click Security in the Connections section.
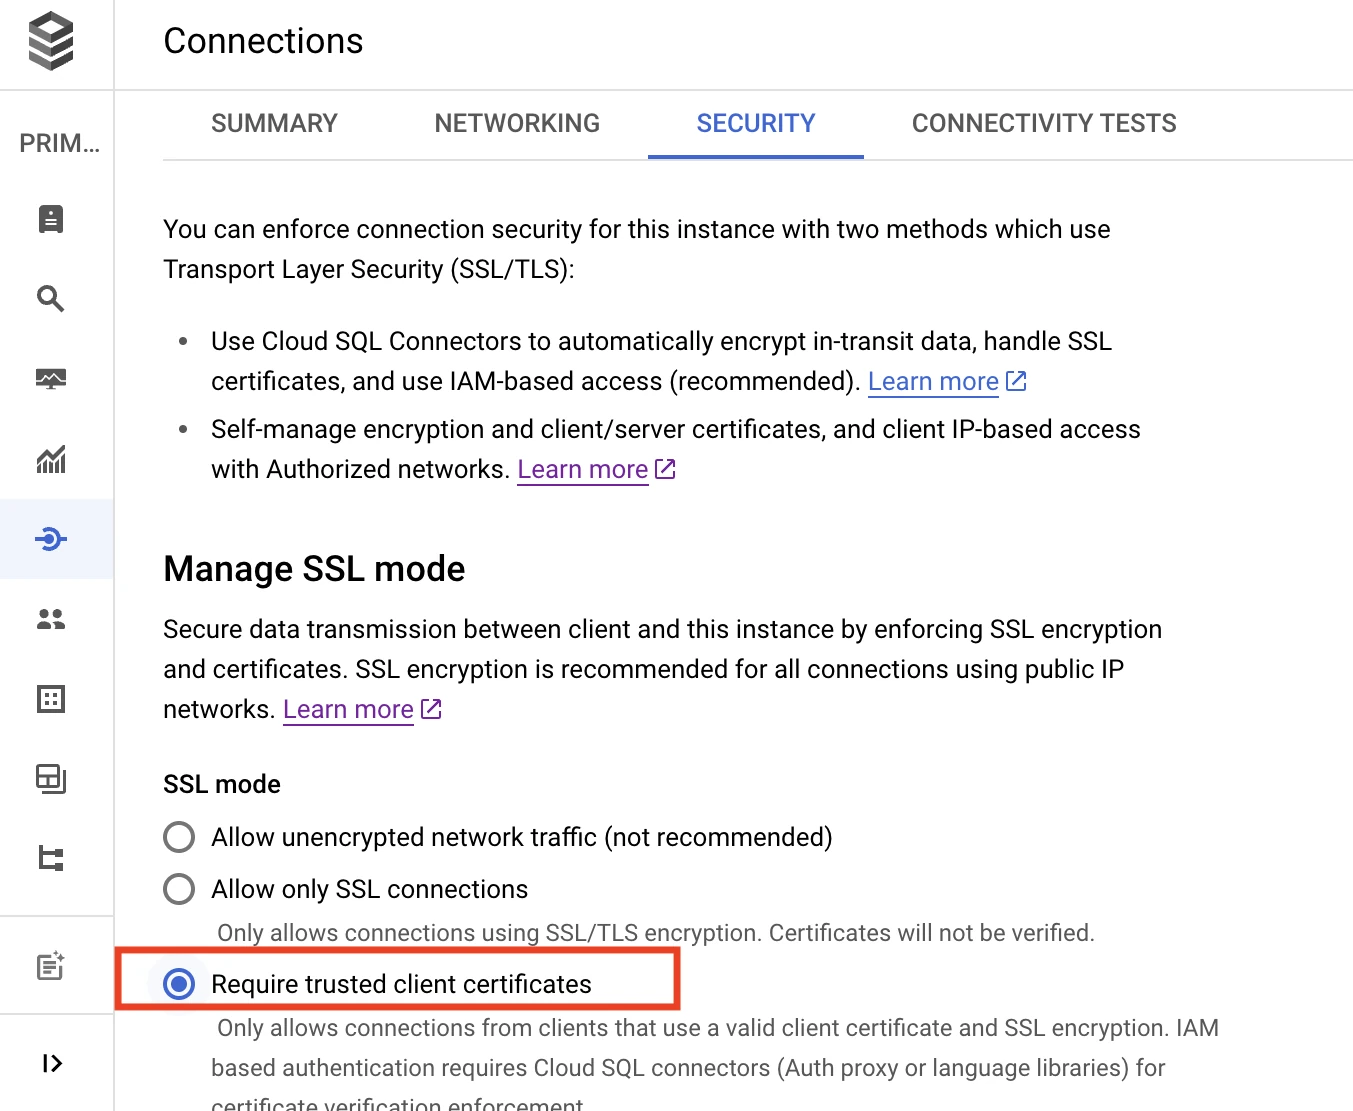
- Select Require trusted client certificates under the Manage SSL mode section.
Heroku Postgres
Enable mTLS by following the instructions in the Heroku documentation. Then, download the client certificate and private key. You need them in the Database access tab if you select the Client certificate authentication method.
Database access
Specify the database-related information required to establish the connection between your database and Fivetran. Also, create a database user and grant the user the required permissions. You must have database administrative access or assistance from a database administrator to configure these settings.
Configure database
In your database, configure the following:
Choose the authentication method you want to use, then complete the corresponding setup steps in your database. Microsoft Entra ID authentication is supported only for Azure Database for PostgreSQL flexible server, while Client certificate authentication is supported only for Google Cloud SQL for PostgreSQL and Heroku Private or Shield instances.
Username and password authentication
Create database user
Create a database user for exclusive use by Fivetran.
Open a connection to your PostgreSQL database in a PostgreSQL console (such as a SQL workbench or psql).
Create a user for Fivetran by executing the following SQL command. Replace
<username>and<password>with a username and password of your choice.CREATE USER <username> WITH PASSWORD '<password>';
Microsoft Entra ID authentication
Configure Microsoft Entra ID authentication
You can use Microsoft Entra ID authentication only when connecting to Azure Database for PostgreSQL flexible server. We support Microsoft Entra ID authentication in the following configurations:
- Connection methods:
- Direct connection
- Azure Private Link
- Incremental sync methods:
- Query-Based
You cannot authenticate using Microsoft Entra ID if you use the logical replication incremental sync method.
To configure Microsoft Entra ID authentication, do the following:
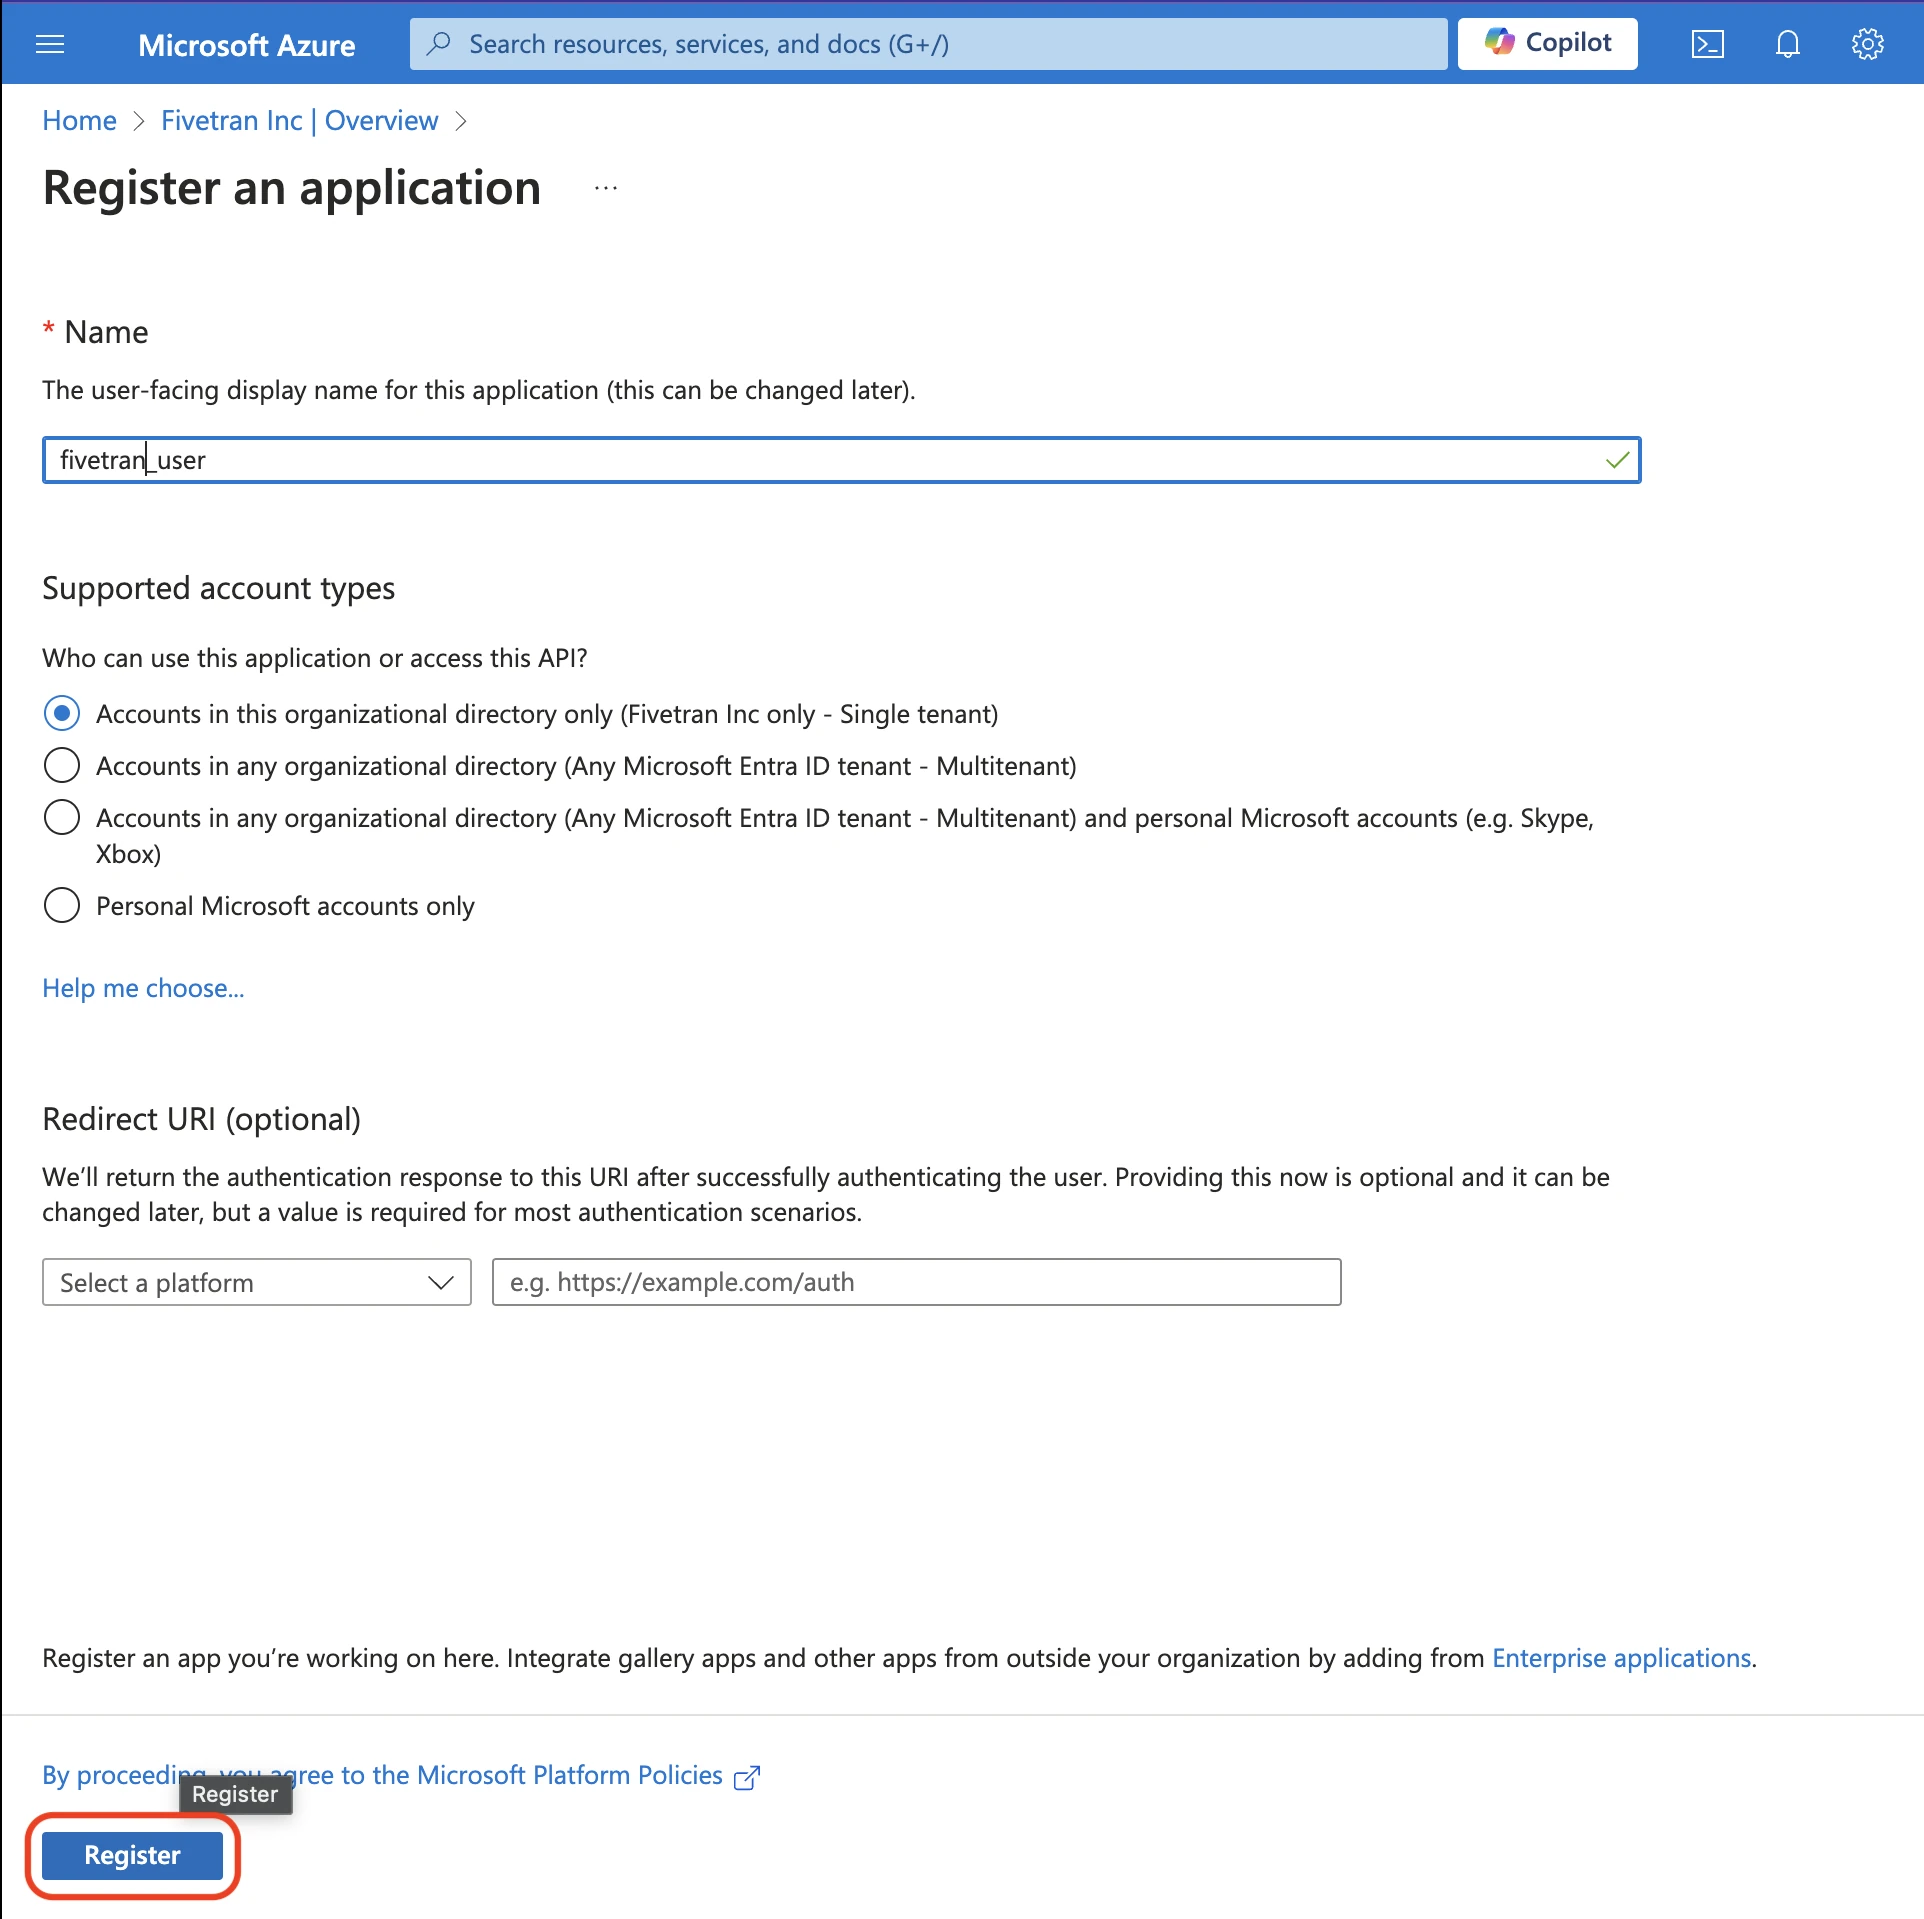
- Register an application in Microsoft Entra ID. For more information, see Microsoft How to Register an App in Microsoft Entra ID documentation.
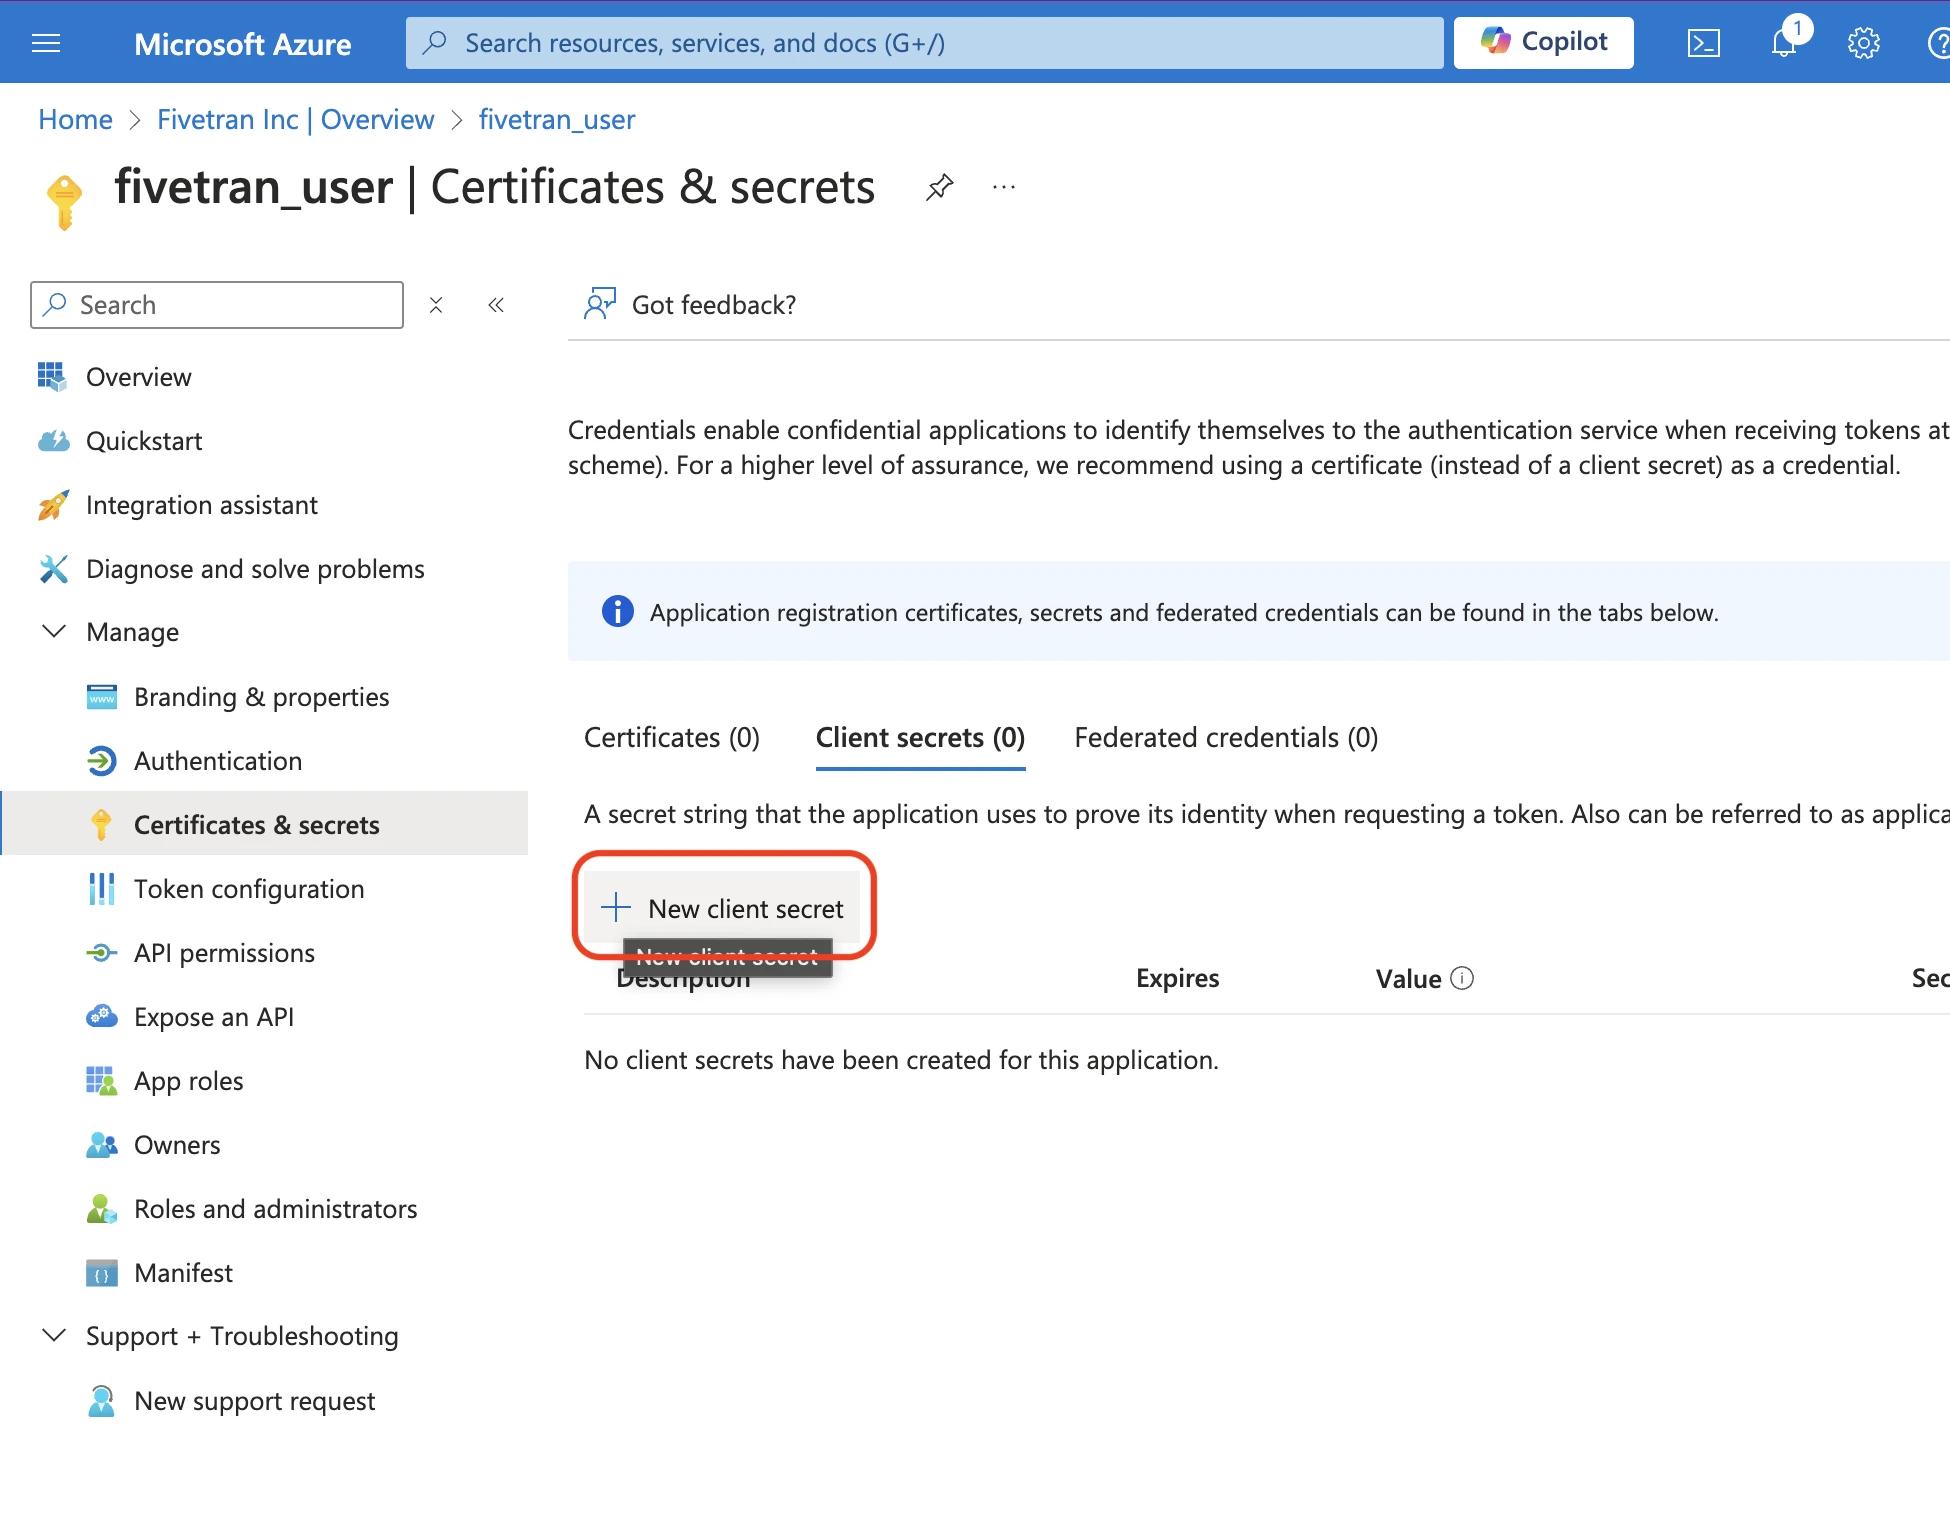
- Add a client secret for the registered application. You must store the generated client secret in a secure location, as you cannot access it later. For more information, see Microsoft Add a client secret documentation.
- In the Azure Database for PostgreSQL flexible server, go to the Authentication section and ensure that one of the following options is selected:
- Microsoft Entra authentication only or
- PostgreSQL and Microsoft Entra authentication
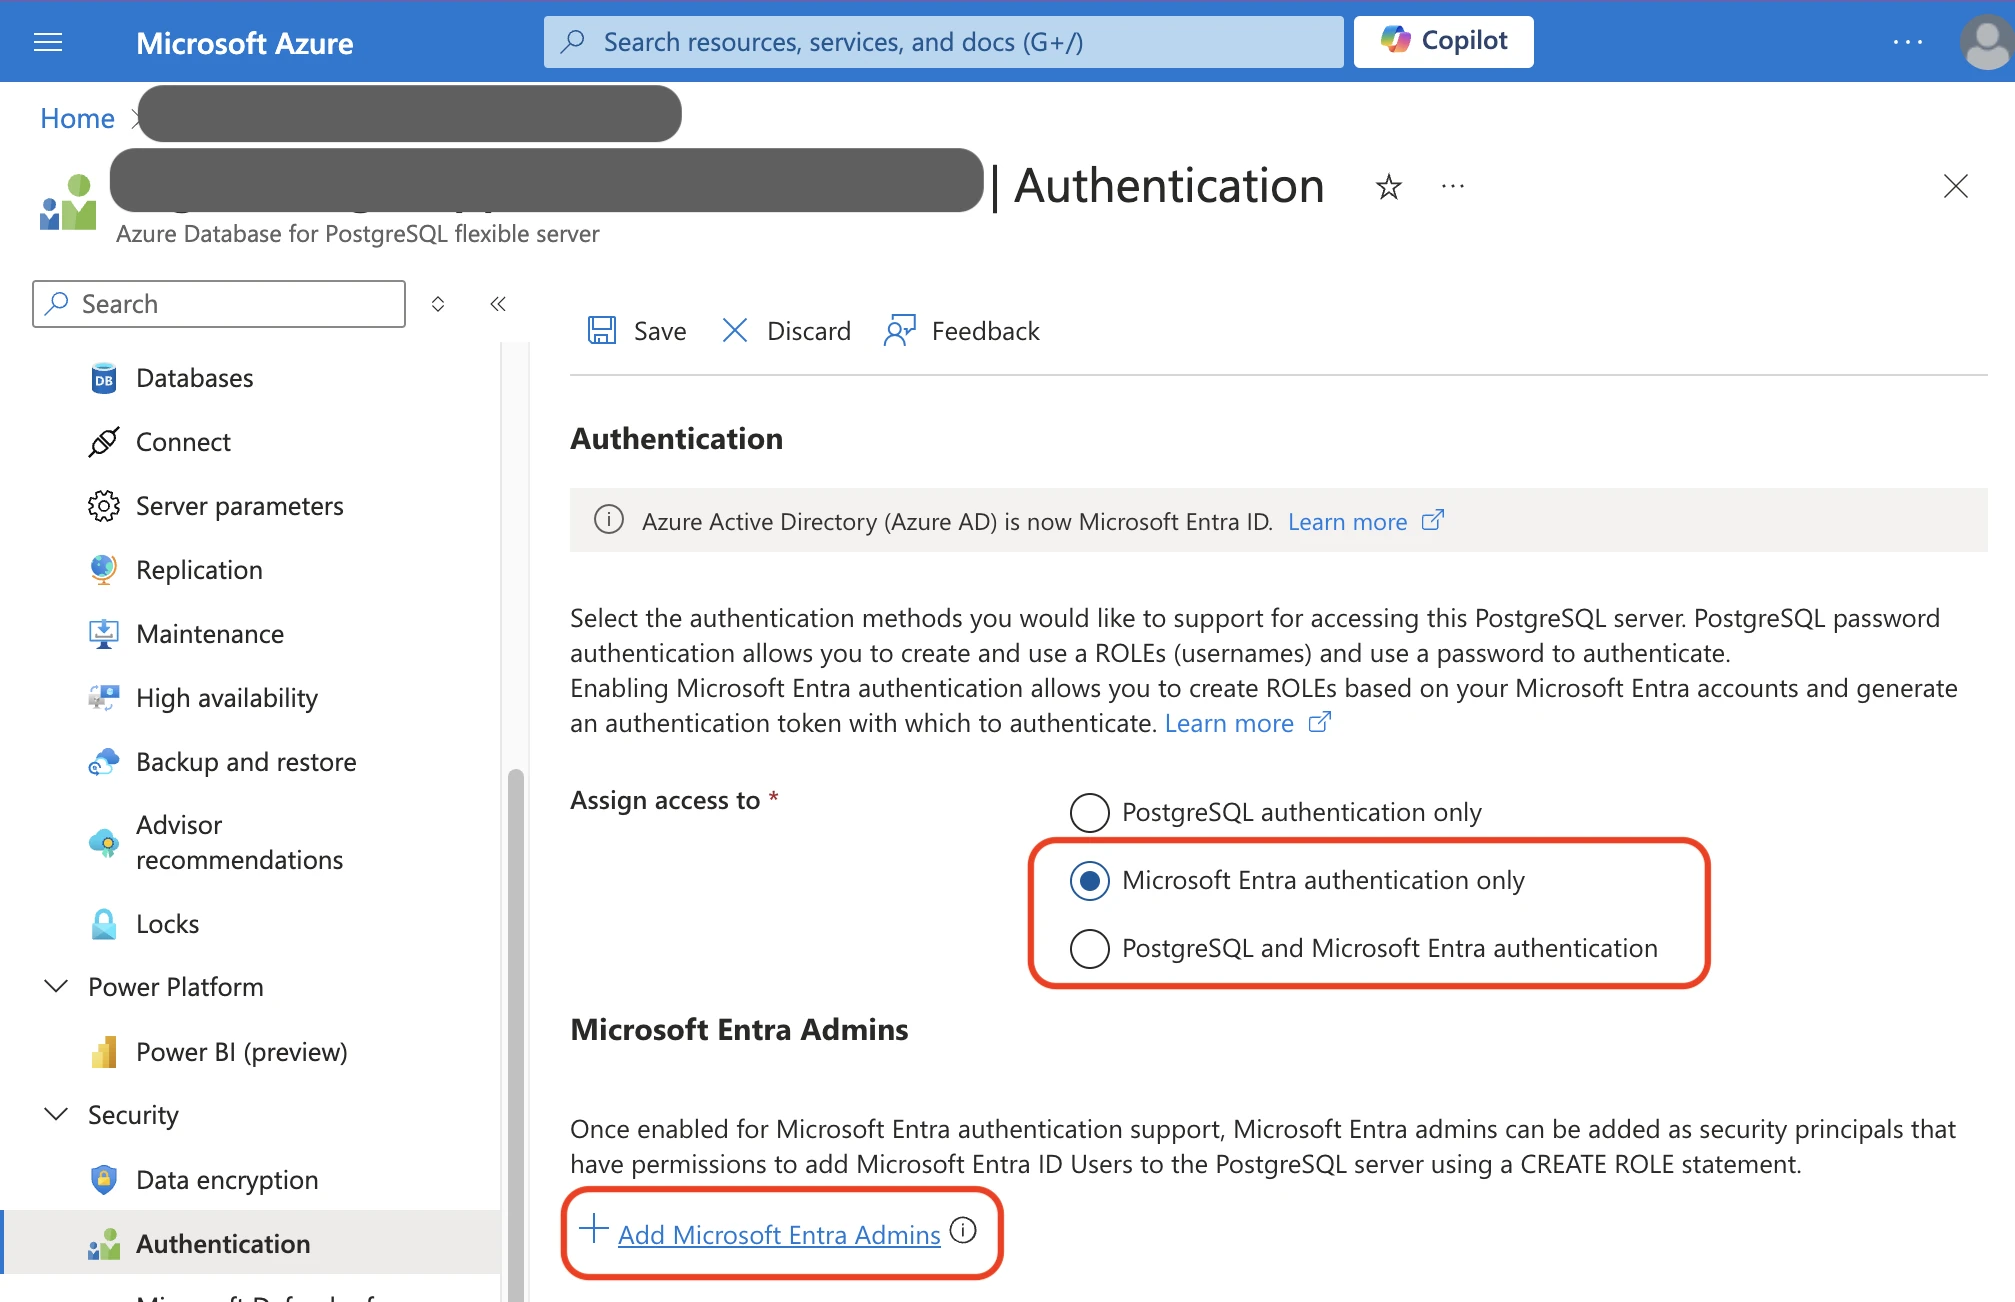
In Azure Database for PostgreSQL flexible server, add a Microsoft Entra Admin if one is not already configured.
Connect to the
postgresdatabase in your Azure Database for PostgreSQL flexible server using the Microsoft Entra Admin's credentials.Add the Microsoft Entra application as a PostgreSQL user using the following command. For more information, see Microsoft Manage Microsoft Entra roles in Azure Database for PostgreSQL - Flexible Server documentation documentation.
SELECT * FROM pgaadauth_create_principal('<application_display_name>', false, false);Replace
<application_display_name>with the display name of the Microsoft Entra application you registered. For example, if you usedfivetran_useras the application display name, replace<application_display_name>withfivetran_user.
Client certificate authentication
Configure client certificate authentication
You can use client certificate authentication with Google Cloud SQL for PostgreSQL and Heroku Private or Shield instances. We support this authentication method through either private networking or a direct connection.
If you have not yet created a client certificate, complete the Configure client certificate step before proceeding.
To create a database user for Fivetran, do the following:
Open a connection to your PostgreSQL primary database in a PostgreSQL console (such as a SQL workbench or psql).
Create a user for Fivetran by executing the following SQL command. Replace
<username>and<password>with a username and password of your choice.CREATE USER <username> WITH PASSWORD '<password>';
Grant the Fivetran user read-only access to the database.
Expand for instructions
Grant read-only access
Grant the Fivetran user read-only access to all tables by running the following commands. To grant access to a schema other than PostgreSQL's default
publicschema, replacepublicwith your schema name. If you want to grant access to multiple schemas, run these commands for each schema.GRANT USAGE ON SCHEMA "public" TO <username>; GRANT SELECT ON ALL TABLES IN SCHEMA "public" TO <username>; ALTER DEFAULT PRIVILEGES IN SCHEMA "public" GRANT SELECT ON TABLES TO <username>;The
ALTER DEFAULT PRIVILEGEScommand ensures that future tables created in the schema are also accessible to the Fivetran user.Restrict access to tables (optional)
You can limit Fivetran's access to specific tables by granting access only to the tables that you want to sync.
You must grant access individually for each table. You cannot grant access to all tables and then revoke access for a subset of tables.
Ensure that the Fivetran user has access to the schema that contains your table(s):
GRANT USAGE ON SCHEMA "your_schema" TO <username>;Revoke previously granted table-level permissions:
ALTER DEFAULT PRIVILEGES IN SCHEMA "your_schema" REVOKE SELECT ON TABLES FROM <username>;
REVOKE SELECT ON ALL TABLES IN SCHEMA "your_schema" FROM <username>;
Grant access to each table:
GRANT SELECT ON "your_schema"."your_table" TO <username>;By default, new tables created in the schema are not accessible to the Fivetran user. To grant access to new tables, run the following command:
ALTER DEFAULT PRIVILEGES IN SCHEMA "your_schema" GRANT SELECT ON TABLES TO <username>;
Restrict access to columns (optional)
You can limit access to specific columns within a table by granting permissions only to those columns.
Revoke existing table-level permissions:
REVOKE SELECT ON "your_schema"."your_table" FROM <username>;Grant access to specific columns:
If you chose Query-Based as your incremental sync method, you must grant us access to the hidden system columns
xminandctid. This speeds up your initial sync and enables capturing deletes. If you chose Logical replication, granting access toxminis recommended for new connections to enable faster initial sync and re-import.GRANT SELECT (xmin, ctid, some_column, other_column) ON "your_schema"."your_table" TO <username>;
After restricting column access, newly added columns will not be accessible automatically. To grant access to new columns, rerun the command above with the additional columns.
Specify database connection parameters
In the Fivetran setup form's Database access tab,
In the Database field, enter the name of your database (for example,
your_database).In the Authentication method drop-down menu, select the authentication method you want to use.
Provide the details required for your selected Authentication method.
Username and password
- In the User field, enter the Fivetran-specific database user that you created earlier.
- In the Password field, enter the password for the Fivetran-specific database user.
Microsoft Entra ID
- In the User field, enter the registered app display name.
- In the Password field, enter the client secret value.
- In the Entra App ID field, enter the registered app client ID.
- In the Azure Tenant ID field, enter the Tenant ID.
Client certificate
- In the User field, enter the Fivetran-specific database user you created earlier.
- In the Password field, enter the password for that user.
- Open the
client-cert.pemfile with a text editor or Terminal. Copy the entire contents of the file, including the header and footer lines. Paste the content into the Client public certificate field. - Open the
client-key.pemfile with a text editor or Terminal. Copy the entire contents of the file, including the header and footer lines. Paste the content into the Client private key field.
Click Next to proceed to the Incremental sync tab.
Incremental sync
Choose and configure the incremental sync method. This determines how Fivetran detects new or changed rows so we don't have to copy the whole table every time. Learn more in our Updating data documentation.
We recommend using the Logical replication method when possible because it is faster and more efficient than Query-Based. For guidance on choosing the best option for your workload, see Logical replication vs Query-Based documentation.
Configure incremental sync in database
In your database, configure the following:
Logical replication
To enable logical replication, perform the following steps:
Go to your PostgreSQL database.
Ensure that your server has ample free space for the logs. As soon as Fivetran processes a log, we delete it. However, we don't delete logs if the sync is interrupted (for example, if we lose access to your database). In this case, logs may accumulate on your server and consume additional storage. The amount of additional disk space that these logs consume is proportional to the number of changes committed on the server. If we can't resume a lost connection quickly enough and you need more disk space, you can drop the replication slot, which deletes its unconsumed logs.
Dropping and recreating the replication slot resets the Log Sequence Number (LSN). Fivetran cannot resume syncing from where it left off, and requires a historical re-sync. For more information, see Data Integrity Issues After Recreating a Replication Slot With the Same Name.
Ensure that the
statement_timeoutsetting on your server is either0(the default value to disable the timeout) or greater than5 minutes.Enable logical decoding using the method appropriate for your PostgreSQL database:
- PostgreSQL: Set the
wal_levelparameter tologicalby addingwal_level = logicalto thepostgresql.conffile. Restart the server for the change to take effect. - Amazon RDS for PostgreSQL: Create a non-default DB parameter group, set
rds.logical_replicationto1, apply the group to the database, and reboot when its status changes topending-reboot. - Amazon Aurora PostgreSQL: Create a non-default DB cluster parameter group, set
logical_replicationto1, apply the group to the cluster, and reboot when its status changes topending-reboot. Configure logical replication on the primary writer, not an Aurora reader. - Azure Database for PostgreSQL: In the Azure portal, set the
wal_levelserver parameter toLOGICAL, save the change, and restart the server. - Google Cloud SQL for PostgreSQL: Set the
cloudsql.logical_decodingflag toonin your Google Cloud SQL instance settings, and then click Done to save the change. - Heroku Postgres: Logical replication is not supported for Fivetran connections. Use Query-Based replication.
Enabling the
cloudsql.logical_decodingflag restarts the Cloud SQL instance. If the primary instance has read replicas, Cloud SQL also enables the flag on the replicas and restarts them in close succession. To control the restart timing, enable the flag on each read replica first, and then enable it on the primary instance.- PostgreSQL: Set the
Set
max_replication_slotsto a value equal to or greater than the number of PostgreSQL connectors that use logical replication plus the number of other replication slots used by your database:- PostgreSQL: Set the
max_replication_slotsparameter in thepostgresql.conffile. - Google Cloud SQL for PostgreSQL: Set the
max_replication_slotsdatabase flag to the required value in your Google Cloud SQL instance settings.
- PostgreSQL: Set the
Set
wal_sender_timeoutto0to disable the timeout:- PostgreSQL: Set the
wal_sender_timeoutparameter in thepostgresql.conffile. - Amazon RDS for PostgreSQL and Amazon Aurora PostgreSQL: Set
wal_sender_timeoutto0in the parameter group. - Azure Database for PostgreSQL: Set the
wal_sender_timeoutserver parameter to0. - Google Cloud SQL for PostgreSQL: Set the
wal_sender_timeoutdatabase flag to0in your Google Cloud SQL instance settings.
For PostgreSQL, if you are configuring high availability (HA) failover, see the Configure high availability and failover (optional) section for additional guidance on this parameter.
- PostgreSQL: Set the
For PostgreSQL 18 and later, configure the replication slot timeout:
- PostgreSQL: Set
idle_replication_slot_timeoutto0to disable the timeout or to at least24hto prevent the replication slot from being invalidated between syncs. - Amazon RDS for PostgreSQL, Amazon Aurora PostgreSQL, and Azure Database for PostgreSQL: Set
idle_replication_slot_timeoutto0or at least24hin the provider's parameter settings. - Google Cloud SQL for PostgreSQL: No action is required because Cloud SQL does not support the
idle_replication_slot_timeoutflag.
- PostgreSQL: Set
Configure client authentication:
- PostgreSQL: Add a record to the
pg_hba.conffile that allows your database to authenticate the Fivetran connection to the WAL. - Google Cloud SQL for PostgreSQL: No action is required because Cloud SQL manages
pg_hba.confautomatically.
- PostgreSQL: Add a record to the
Set
max_wal_sendersto at least twice the total number of logical replication slots. For example, if your database uses 11 replication slots, setmax_wal_sendersto22or greater:- PostgreSQL: Set the
max_wal_sendersparameter in thepostgresql.conffile. - Google Cloud SQL for PostgreSQL: Set the
max_wal_sendersdatabase flag to the required value in your Google Cloud SQL instance settings.
- PostgreSQL: Set the
Using a PostgreSQL console, such as a SQL workbench or
psql, log in to your primary database using an appropriately privileged user:PostgreSQL: Log in as a superuser.
Amazon RDS for PostgreSQL and Amazon Aurora PostgreSQL: Log in as a user with the
rds_superuserrole.Azure Database for PostgreSQL: Log in as an administrator with
REPLICATIONpermission. If necessary, runALTER ROLE <admin_role> WITH REPLICATION;before continuing.Google Cloud SQL for PostgreSQL: Log in as a user with the
cloudsqlsuperuserrole. The defaultpostgresuser has this role. If the user does not have permission to create a replication slot, run the following command before continuing:ALTER USER postgres WITH REPLICATION;
Create a publication for your tables. If you want, you can create a publication for only certain tables so that you add or remove tables from the publication later on. Only changes from tables in the publication are replicated to Fivetran. Each database can have multiple distinct publications. You must have
CREATEprivileges or above to run this command.The publication name
fivetran_pubquoted throughout this guide is used purely as an example. The actual publication name should be unique for every database and cannot start with a number.CREATE PUBLICATION fivetran_pub FOR TABLE table2, table4, table8;To add or remove a table from a publication, run the following command. You must have ownership rights over the table(s).
ALTER PUBLICATION fivetran_pub ADD/DROP TABLE table_name;Alternatively, you can create a publication for all of your tables. However, you cannot remove any table from this publication later on. You must have superuser privileges (or
cloudsqlsuperuseron Google Cloud SQL) to run this command.CREATE PUBLICATION fivetran_pub FOR ALL TABLES;(Optional) You can choose which operations to include in the publication. For example, the following publication includes only
INSERTandUPDATEoperations.CREATE PUBLICATION insert_only_pub FOR TABLE table1 WITH (publish = 'INSERT, UPDATE');To add partitioned tables for PostgreSQL version 13 or later, run the following command to enable publish_via_partition_root.
CREATE PUBLICATION fivetran_pub FOR ALL TABLES WITH (publish_via_partition_root=true);Create a logical replication slot for the database you want to sync by running the following command. You must use the standard output plugin
pgoutput. Ensure that you are connected to the correct database when you create your replication slot, or your connection will not be able to find the slot.You must create a unique replication slot for every connection that uses the same PostgreSQL cluster. Replication slot names cannot start with a number. (The replication slot name
fivetran_pgoutput_slotquoted throughout this guide is used purely as an example.)You need to create the replication slot after you have created the publication.
SELECT pg_create_logical_replication_slot('fivetran_pgoutput_slot', 'pgoutput');If your PostgreSQL server version is 16 or later and you want to sync from a standby, create the replication slot based on your deployment type:
- For a cluster deployment, create the replication slot on the primary.
- For a non-cluster deployment, create the replication slot on the standby.
Verify that your chosen tables are in the publication.
SELECT * FROM pg_publication_tables;Grant the Fivetran user permission to read the replication slot.
PostgreSQL, Azure Database for PostgreSQL, and Google Cloud SQL for PostgreSQL:
ALTER ROLE <username> WITH REPLICATION;Amazon RDS for PostgreSQL and Amazon Aurora PostgreSQL:
GRANT rds_replication TO <username>;
Log in as the Fivetran user.
Verify that the Fivetran user can read the replication slot by running the following command. Replace
fivetran_pgoutput_slotwith your replication slot name andfivetran_pubwith the publication name.SELECT count(*) FROM pg_logical_slot_peek_binary_changes('fivetran_pgoutput_slot', null, null, 'proto_version', '1', 'publication_names', 'fivetran_pub');If the query succeeds, then permissions are sufficient.
You must periodically tune the checkpoint_timeout and max_wal_size parameters based on your PostgreSQL database operations. If you do not, you may experience replication failures. To learn how to tune, read this tuning checkpoints documentation.
Configure high availability and failover (optional)
If you use a high-availability (HA) deployment, ensure that the logical replication slot used by your Fivetran connection is synchronized between the primary and standby servers.
Expand for details
For PostgreSQL 17 and later, use PostgreSQL's built-in sync_replication_slots parameter to enable replication slot synchronization. For more information, see PostgreSQL's Replication Slot Synchronization documentation.
For PostgreSQL 11 through 16, configure the pg_failover_slots extension with the following PostgreSQL and extension settings to support Fivetran failover. For complete installation and configuration instructions, see EnterpriseDB’s Installing PG Failover Slots and Configuring PG Failover Slots documentation.
On the primary server, set the
wal_sender_timeoutparameter to0or a value of at least5min. The extension's slot synchronization loop can hold the WAL sender, and values between1msand30smay cause the server to forcibly close the connection. We recommend5minor0(unlimited).On the primary server, set the
pg_failover_slots.standby_slot_namesparameter to a comma-separated list of the physical standby replication slot names. The extension uses these slots to synchronize the logical replication slot during failover.For example, if your physical standby replication slots are named
standby_db01andstandby_db02, configure the parameter as follows:ALTER SYSTEM SET pg_failover_slots.standby_slot_names = 'standby_db01,standby_db02'; SELECT pg_reload_conf();If the configured standby replication slots do not meet the requirements of
pg_failover_slots.standby_slots_min_confirmed, the extension stalls WAL delivery and Fivetran syncs pause. For more information, see thepg_failover_slotsdocumentation.On each standby server, verify that the
pg_failover_slots.synchronize_slot_namesparameter matches the Fivetran replication slot. This parameter defaults toname_like:%, which synchronizes all logical replication slots, but if it has been customized, it must either keep matching your Fivetran replication slot name or be updated to include it. Otherwise, the replication slot won't exist on the standby server(s) after failover, and Fivetran syncs fail.For example, to synchronize only your Fivetran replication slot named
fivetran_slot, run the following on each standby server:ALTER SYSTEM SET pg_failover_slots.synchronize_slot_names = 'name:fivetran_slot'; SELECT pg_reload_conf();Before promoting a standby to primary, verify that the Fivetran replication slot has finished synchronizing to that standby. Query
pg_replication_slotson the standby server:SELECT slot_name, active FROM pg_replication_slots WHERE slot_name = 'fivetran_slot';The slot must exist and have
activeset tofalse. If the slot is missing oractiveistrue, it is still initializing and is not yet ready for failover. For more information, see thepg_failover_slotsreadiness guidance.
Query-Based
Fivetran runs SQL queries that read PostgreSQL system columns (xmin and, when applicable, ctid) to detect new and changed data during each sync.
Capture Deletes (optional)
Query-Based sync detects deleted rows by default. You can disable this behavior by turning off the Capture Deletes toggle in the connection setup form.
When Capture Deletes is enabled:
Fivetran adds an internal helper column
ctid_fivetran_idto each synced table. Fivetran uses this column to track deletes by storing the row'sctidvalue at the end of each sync.- Before the initial sync (new connection): Fivetran creates tables with
ctid_fivetran_idduring the initial sync. No additional re-sync is required. - After data is already synced (existing connection): Fivetran runs a one-time migration sync of the selected tables to populate
ctid_fivetran_idcolumn and capture a snapshot of the source table. This migration sync does not trigger a table re-sync. It may take longer than a regular sync because Fivetran must populate the additionalctid_fivetran_idcolumn.
- Before the initial sync (new connection): Fivetran creates tables with
This setting is permanent for the connection. After you click Save & Test in the connection setup form, it’s locked and can’t be disabled later, whether or not the connection has run its first sync.
We sync partitioned tables using child-to-child sync only.
For details and limitations, see our Capturing deletes documentation.
Query-Based sync requires full table scans to detect updates and may be slower than logical replication, especially for large tables. In high-write databases, PostgreSQL xmin freezing/wraparound can also cause older rows to be re-synced, increasing sync volume and load on your PostgreSQL source database. If possible, use logical replication.
Fivetran Teleport Sync Sunset
We have sunset Teleport Sync, and it is no longer available as an Incremental sync method option in the connection setup form for new connections.
You do not need any additional configuration for the Teleport Sync method. We automatically create the aggregate function (bit_xor) required for the Teleport mechanism.
However, if you are connecting to a standby or read replica, you must manually create this aggregate on the primary database because new objects cannot be created directly in read replicas. Run the following SQL command on your primary database as the Fivetran user:
CREATE AGGREGATE BIT_XOR(IN v bigint) (SFUNC = int8xor, STYPE = bigint);
Creating the aggregate on the primary ensures that it is replicated to the standby or read replica, allowing Teleport Sync to function correctly.
Specify replication parameters
In the Fivetran setup form's Incremental sync tab,
- In the Incremental sync method tab, select the incremental sync method that you want to use:
- Logical Replication: Enter the Replication Slot name and Publication Name that you created in the Configure incremental sync method - Logical replication step.
- Query-Based: The Capture Deletes toggle is ON by default. Fivetran uses this to detect deleted rows. Once you save the connection, this setting cannot be changed. Turn the toggle OFF before saving if you don't want to capture deletes. For more information, see Capture deletes.
Click Save & Test. Fivetran tests and validates the connection to your PostgreSQL database. After the tests are completed successfully, follow the prompts in the Fivetran dashboard to begin your initial sync.
Setup tests
Fivetran performs the following tests to ensure that we can connect to your PostgreSQL database and that it is properly configured:
- The Connecting to SSH Tunnel Test validates the SSH tunnel details you provided in the setup form. It then checks that we can connect to your database using the SSH Tunnel. (We skip this test if you aren't connecting using SSH.)
- The Connecting to Host Test validates the database credentials you provided in the setup form. The test verifies that the host is not private and then checks the connectivity to the host.
- The Validating Certificate Test generates a pop-up window where you must choose which certificate you want Fivetran to use. It then validates that certificate and checks that we can connect to your database using TLS. (We skip this test if you selected an indirect connection method and then disabled the Require TLS through Tunnel toggle.)
Amazon Aurora PostgreSQL does not return the entire certificate chain, so the root certificate may not be selectable during this test.
- The Connecting to Database Test checks that we can access your database.
- The Connecting to WAL Replication Slot Test confirms that the database associated with the replication slot matches the name you supplied in the setup form. It then verifies that the replication slot uses the
pgoutputplugin. Lastly, it makes sure that the Fivetran user has replication privileges. (We skip this test if you selected Query-Based as your incremental sync method) - The Checking Configuration Values Test checks a set of WAL-configured values against the recommended settings and detects if they are below the recommended range. (We skip this test if you selected Query-Based as your incremental sync method.)
- The Publication Test verifies that the supplied publication name exists in your database. (We skip this test if you selected Query-Based as your incremental sync method.)
The tests may take a few minutes to finish running.