

Your data lake: Automated, governed, and secure
Use Lake Compute to run dbt transforms directly over the lake, preparing and analyzing your data without provisioning any extra infrastructure, or bring your own compute. From reliably moving data from 750+ sources into your lake, to transform execution, to ongoing table maintenance, Fivetran takes the complexity out of data lake management
Drive greater value with a flexible, scalable data lake foundation

A trusted foundation for AI/ML workloads
Create a universal storage layer for all data types, where analytics and AI systems run on a single, trusted source of truth.

Lower ingestion costs
Fivetran covers the data movement costs of landing data into your lake, every engine reads from one copy eliminating duplicate data stores
Implement Open Data Infrastructure
Eliminate vendor lock-in and future-proof your data strategy by switching to Apache Iceberg™ tables. Learn more here.
Connect any engine
Your CDW becomes a first class query engine, utilize other engines for their specific benefits.
A new serverless compute engine built for running dbt models.
Read the docs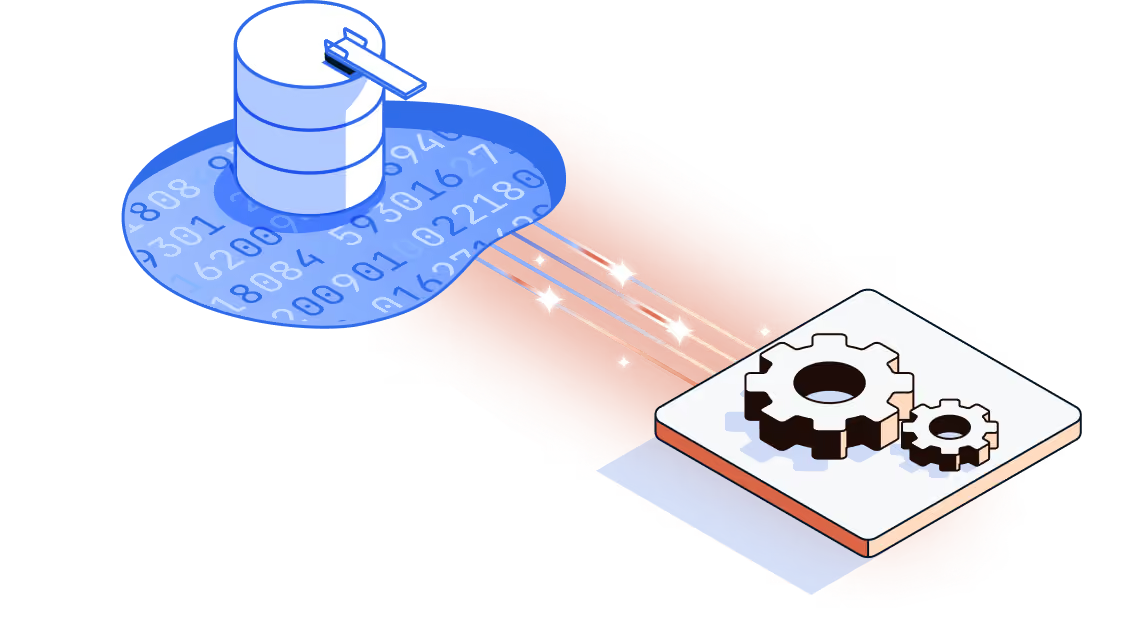
"We've been impressed by the flexibility Lake Compute gives us. Previously we were locked into a single data warehouse. Now we can choose where each dbt workload runs, and use whichever engine actually fits the job."


Designed for dbt workloads
Lake Compute materializes your transform model output into open and interoperable Apache Iceberg tables.

No infrastructure to set up or maintain
Lake Compute materializes your transform model output into open and interoperable Apache Iceberg tables.

Save your compute capacity
Lake Compute materializes your transform model output into open and interoperable Apache Iceberg tables.
See how you can land analytics-ready data in your lake in minutes

Trusted by thousands of data-driven companies




Explore Fivetran’s supported data lake destinations in depth




Your data lake: Automated, governed, and secure
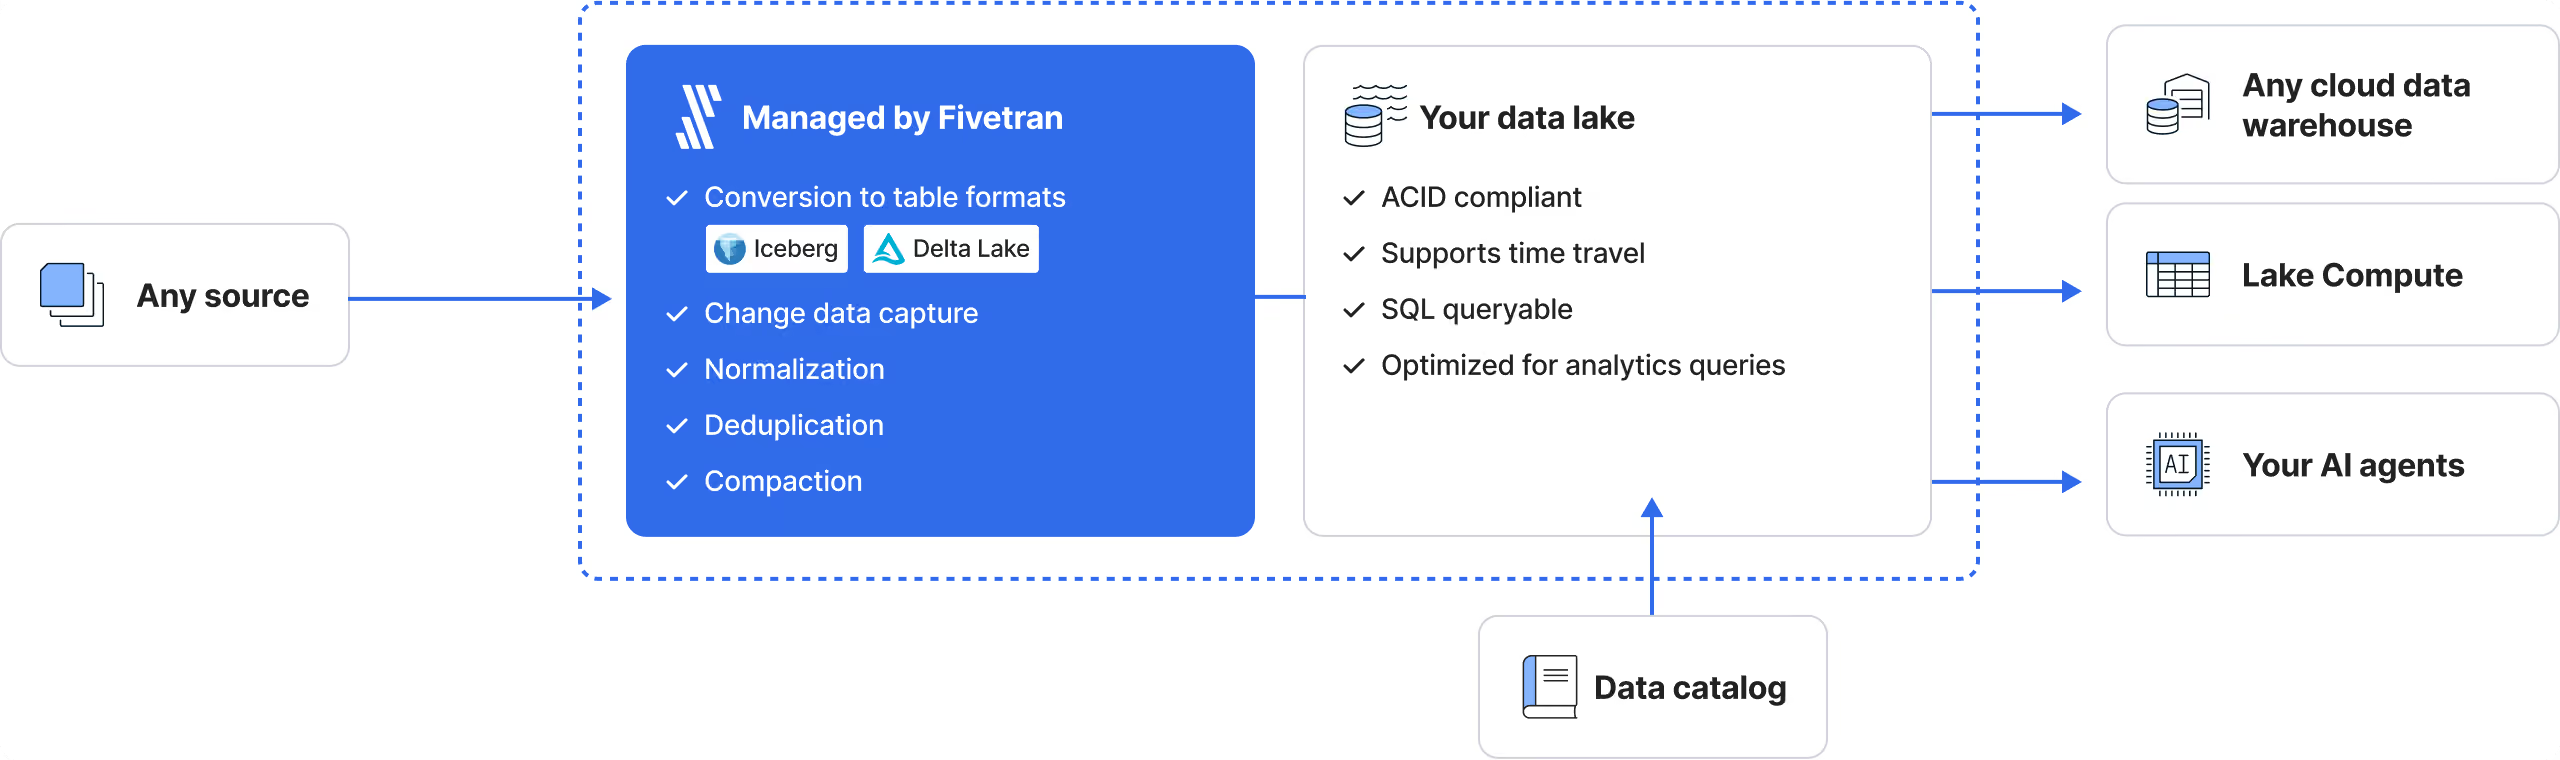
Fivetran automatically normalizes, compacts, and deduplicates your data before standardizing it in Iceberg and Delta Lake table formats for downstream discoverability and interoperability. From securely and reliably moving data from 700+ sources into your data lake to continuous table maintenance and updates, Fivetran removes the complexity from your data lake management.
The enterprise standard for data lake integration


Fivetran’s Managed Data Lake Service gives us the flexibility to direct data anywhere we want and consume it any way we want. We can choose what to bring into the warehouse or send elsewhere, which has reduced our costs, increased security, and improved our data governance.

The hard ROI of Fivetran for us is time savings, but the real impact goes beyond that. As a Fivetran customer and partner, we gain peace of mind, strategic agility, and the confidence to focus on what truly matters: delivering unique, personalized solutions for our clients.
Dive into data lakes with Fivetran

FAQS
For any existing connections the Fivetran team can help you migrate existing data and connections to your data lake. Reach out to your account manager or ask support for help.
Ideal for more simple models that's don't rely on large joins or large window functions, Lake Compute is ideal for running models to prepare your ingested source tables for down-stream analytics.
Within a single dbt project you can choose which models run on Lake Compute and which run on your cloud data warehouse - allowing you to use the right tool for the job while optimizing costs.
Automate your data lake management today
Land fully managed, query-ready data in your lake of choice with Fivetran.

Apache Polaris and Apache Iceberg are trademarks of the Apache Software Foundation.